The DJ Who Shuffled Every Song and Still Got Track Seven

The DJ Who Shuffled Every Song and Still Got Track Seven

About halfway through a twelve-track album, the DJ hears a familiar transition. The sixth song has just ended, the opening notes of the next one come through the speakers, and somebody at the other end of the room says, “I thought you put this on shuffle.” The DJ checks the display. Sure enough, the seventh song on the album is playing seventh.

I sympathize with the listener. If I bothered to shuffle an album and then heard a song exactly where I expected to hear it, I might check the display myself. But before we send the equipment out for repair, let me offer a wager. Which is more likely on a fair shuffle: that every song moves to a different position, or that at least one winds up right where it started?

I’ll take the second bet. On a twelve-track album, it wins about 63.2 percent of the time.

A three-song experiment

Let’s give the DJ a three-song EP and call the tracks A, B, and C. They appear on the original recording in that order. For our experiment, the player uses each song once, and each of the six possible running orders has the same chance of appearing. You can check the wager yourself by covering the right-hand column and looking for songs that kept their seats.

Running order Songs in their original positions
ABC A, B, and C
ACB A
BAC C
BCA None
CAB None
CBA B

Only BCA and CAB move every song. Even playing the album backward leaves B sitting comfortably in the middle. Four of the six orders give our suspicious listener something to point to, so the bet on at least one match wins two times out of three.

The two orders in which everything moves have a name. Mathematicians call each one a derangement, a word I would have reserved for the fellow keeping written records of what the DJ played.

When did you make your prediction?

Back at the twelve-track album, suppose you write “track seven will play seventh” on a slip of paper and hand it to the DJ before he presses shuffle. Only one of the twelve slots will satisfy that prediction. Your chance of being right is one in twelve, or about 8.3 percent.

Now put the pencil away and listen to the whole album. If track two plays second, you can point that out. If track nine plays ninth, you can point that out just as readily. By the end of the evening, you may remember one striking coincidence, but the shuffle had twelve opportunities to supply it.

There is a wrinkle in working out those odds. The twelve opportunities depend on one another because every song uses up a slot. Imagine that eleven songs have somehow kept their original positions. Where, exactly, do you propose to put the twelfth?

One song, on average

We can answer one question without untangling those dependencies. If the DJ shuffles the album night after night, how many songs per night should he expect to find in their original positions?

Consider the three-song experiment again. Read down the right-hand column and count the matches: three, one, one, zero, zero, and one. That makes six matches distributed across six equally likely playlists, for an average of exactly one. The original order, ABC, contributes three matches all by itself, enough to balance both evenings when nothing matched.

The same reasoning works for twelve songs. Each song has a one-in-twelve chance of keeping its position, so adding the twelve individual chances gives an expected count of exactly one. Put a hundred songs on the playlist, and the arithmetic becomes a hundred times one hundredth. I rather like that trade: every individual prediction gets worse, yet the expected number you get right stays precisely where it was.

Where the 63.2 percent comes from

The average count leaves one piece of the wager unsettled. A playlist with three matches earns the listener the same single win as a playlist with one, so we need to count playlists with a match. We can do that by correcting for the occasions we counted twice, then correcting for the occasions that correction went too far.

The three-song EP shows it in action. Adding the individual matches gave us six, but ABC appeared in that count three times. Subtract the three overlapping pairs of matches, all of which belong to ABC, and we have erased that playlist altogether. Add it back once for the three-way overlap, and the count comes out right: six minus three plus one gives four winning playlists.

For a twelve-track album, the same bookkeeping gives the following probability. The exclamation point means factorial, so, for example, 4! is the product of 4, 3, 2, and 1.

P(\text{at least one match}) = 1 - \frac{1}{2!} + \frac{1}{3!} - \frac{1}{4!} + \cdots - \frac{1}{12!}

Those fractions get small in a hurry. The first four terms already give 62.5 percent, and carrying the calculation through the twelfth gives approximately 63.212 percent. As the playlist grows, the probability approaches a familiar mathematical quantity in an unexpected setting: one minus the reciprocal of Euler’s number. Rounded to three decimal places, that limit is 0.632.

The DJ makes a small adjustment

By the following weekend, the DJ has devised a cure for the complaints. He lets the player generate a playlist, checks it against the back of the CD case, and presses shuffle again if even one song has kept its slot. Eventually a playlist passes inspection, and the evening proceeds without incident.

I wonder how many listeners would judge the new arrangement an improvement. Every song now goes somewhere else, which was what they expected from shuffle in the first place. All the DJ had to do to make his twelve-track album sound properly random was throw away nearly two-thirds of the orders a fair shuffle would have given him.


What I Used To Think About When I Thought While Running

A pseudo-review of Haruki Murakami’s What I Talk About When I Talk About Running

Author’s Note: Haruki Murakami is a perennial contender for the Nobel Prize in Literature; I am not. He has run over 25 marathons; I have 6 under my belt. He might run more; I certainly will not. My right hip is in bad shape, as are numerous other joints. He has sold over 150,000,000 books; I have not. I don’t think he’ll be awarded a Nobel Prize because he sells way too well. Historically, the prize goes to authors who are not popular. Even though I am not popular, I also will not be awarded any such prize. That said, he and I do have some things in common, and I greatly admire him. Let’s get to work.

I used to write pretty much all my blog posts from ideas that came to me while running. I wrote the pieces later, slowly at the keyboard, but the idea came to me during the run. A random thought would become interesting as the miles clicked off. Two or three things (almost invariably three) that I’d never thought of putting together would suddenly seem to be connected. By the time I’d sat down to write, I’d have a full outline.

I’m older now, and that particular creative process is over. I miss coming home from my runs with lots of ideas. Running had become an integral part of how I thought, and I’d gotten used to finding ideas in it. Now I get absolutely nothing. I suppose it’s just the normal thing with age (alongside the fact that I’m pretty much in pain in all the right joints as I hobble along at a sub-14:00 pace).

That’s the personal baggage I bring to Haruki Murakami’s What I Talk About When I Talk About Running. It’s a memoir about his relationship between running and writing, viewed through the lens of training, memory, and reflection on his own work. The NYC Marathon is the catalyst for the book, but the real interest lies in the routine habits that accompany the work. In some sense, we are kindred spirits.

Murakami writes about those little habits with a most engaging lack of fuss. The weather, the music, the mileage, and the sheer practicality of fitting one thing into another’s schedule all are addressed. I quite like the amount of attention he pays to the mundane. A life spent writing still involves many hours of deciding when to get up, what to do next, and whether you’ve got the energy to do it. And let me tell you, the energy part comes into clear focus as I age.

There’s a very interesting difference between his experience and mine. Murakami describes running as a way to calm the mind. My runs used to generate thoughts that I wanted to keep. What I see in his description, though, is the relief of being able to step away from the need to make every thought useful. In my case, the useful thought seemed to like being left to itself; it was happy to be a passing thought.

I can’t actually explain why it worked. Maybe it was just the repetition. Maybe the idea needed time to grow up in its own right rather than me just sitting on it and demanding an answer. I’m not in any position to give a scientific explanation of something I know essentially through experience (imagine that?!). All I know is that I went running and came back with stuff to write about.

The setup was absolutely ideal for a writer. You didn’t need to make a separate appointment to sit down and think of a subject. Thinking was part of the activity you were already engaged in, and the writing simply grew out of that. Only now do I realize how much of the work was done before I even got to the desk.

Muraki’s view is that you have to leave yourself enough energy for the next run. You have to be able to stop a day’s writing and still have something to say. His point is about continuity, really, about being able to go back the next day. I think that’s a more useful observation than any sweeping statement about inspiration. If you’re writing regularly, you’re going to wake up the morning after a good idea and still have a lot of work to do.

Still, I have issues with the running and writing comparison. You can take it too far. Writing involves false starts, wrong turns, and there are days when the only thing you can do is delete a paragraph rather than add a page. Tenacity matters, but so does recognizing when what you have been doing needs to change.

That’s also where the book’s small size is both a real strength and a real limitation. The observations are very accessible, and you do get a sense of things, but they don’t always go on to really explore the creative process. If you’re looking for a detailed insight into how a particular novel was written, you may be disappointed. I’m one of those people who sometimes does want more. For me, the book is at its best as the company of someone who has spent a lifetime thinking about this.

It’s all the more pertinent in the context of aging. Murakami talks about continuing to train as his marathon times get worse and the difficulty of accepting what those times tell him. The relationship between effort and improvement which has always held true, starts to fall apart. That’s a very unsettling experience, particularly when that same relationship has worked for you for so many years.

Over four decades ago, “The Beav” and I used to go for 10-mile training runs. We would finish in under an hour with no difficulty, talking as we cruised through a local, well-known park. Now I cannot run 6 miles in an hour. Honestly, I can not get close. Is there a relationship between inspiration and speed? I’ll leave that for a later post. As of now, I have no idea. All I know is that I am slow and uninspired.

My disappointment is harder to quantify. There’s no record of when running stopped supplying me with ideas for my posts. All I have is the memory of how easily it used to do so, contrasted with the reality that it doesn’t anymore.

I link that change to aging, though I can’t prove age is the explanation. The experience is different; the explanation is less clear. I’d rather own up to that uncertainty than turn a personal bereavement into some sort of universal rule about what happens to us all.

What I miss is the ease of it. A very significant part of my life used to dovetail with another very significant part without any negotiation at all. Running and writing went hand in hand. Now I have to think about a relationship I once took for granted, which is, of course, something familiar to anyone who’s been around long enough to see an old routine change.

Murakami is the perfect example of that, as he absolutely allows for dissatisfaction. His love of running makes room for fatigue and disappointment. That’s what gives the book its weight. You can love a pursuit and still admit it’s gotten harder, that it doesn’t always pay off as much as it used to.

I’d particularly recommend What I Talk About When I Talk About Running to people whose lives are organized around a single activity. The book’s appeal lies less in the mileage Murakami covers than in how a repetitive act can become part of your sense of self. It’s very restrained in its prose, very personal in its scope, and the insights build up slowly. Some people will find that a bit thin, I’m sure; I think much of its value is in the space it leaves for my own experience.

For years, running was integral to my creative process. I had no idea how long that would last, and I certainly never thought to ask. Murakami’s book has helped me appreciate the arrangement far more now. However, appreciation alone does nothing to lessen the fact that I usually come home from a run too tired to do anything but sit on the floor.

I’d still like to come back from a run with the notion that I ought to sit down and write. Hope springs, but I am not counting on a return to my glory days,

 Postscript

Well, it appears I have lied throughout this essay, both on purpose and by omission. I know exactly why I am no longer inspired when I go for runs. I also refused to tell you why I read the book in the first place. Both situations involve much younger women who caught my attention. I guess I didn’t mention either of them because every author has a serious decision to make: how much of themselves are they willing to reveal to a total stranger, someone they do not know and will never meet. In this instance, I decided to do the opposite of what I have done in previous posts; I invoked my Fifth Amendment privilege and moved on.


The Keystone Decade: Finding the Best Second Baseman of the 1990s

Second base has always occupied an unusual place on a baseball field.

It is a middle-infield position, so defense matters. The second baseman has to turn double plays with runners bearing down on him, range into the hole, cover first base on certain plays, move toward the bag on steals, and function almost continuously in partnership with the shortstop. Yet second base has rarely demanded the extraordinary arm strength traditionally expected from the other side of the bag.

That difference has allowed the position to attract many kinds of players. Some second basemen have been glove-first specialists. Others have been contact hitters, base stealers, leadoff men, or middle-of-the-order bats whose offense carried most of their value. The greatest ones have usually been something more difficult to classify. They could hit, field, run, and remain productive long enough that no single part of their game adequately described them.

The 1990s offer a particularly interesting decade to study this balance.

Roberto Alomar (the best I have ever seen) was in his prime. Craig Biggio was transforming himself into one of baseball’s most productive offensive players. Chuck Knoblauch emerged as an exceptional leadoff hitter. Ryne Sandberg was completing a great career. Lou Whitaker was doing the same, though with considerably less attention. Carlos Baerga had a brilliant stretch in Cleveland. Jeff Kent began the career that would eventually make him one of the greatest offensive second basemen ever.

The names are familiar. The ordering is less obvious.

So I wanted to approach the question the same way I approached the shortstops of the 1970s. Rather than begin with awards, reputation, Hall of Fame status, or memory, I began with the numbers.

The question was simple enough: Who was the best second baseman of the 1990s?

The answer turned out to be unusually clear, but, as usual, the story underneath was much more interesting.

Defining the Decade

The study covers the 1990 through 1999 seasons. The initial player pool required at least three qualifying seasons at second base during the decade. That threshold is deliberately permissive. It prevents a single good season from dominating the discussion while still allowing players whose careers began or ended during the decade to participate.

This is particularly important for players such as Ryne Sandberg and Lou Whitaker. Neither player’s career fits neatly inside the decade. Sandberg’s prime began before 1990, while Whitaker was already well established by the time the decade opened.

A rigid ten-season requirement would therefore answer a different question. It would identify the player who most completely occupied the decade rather than the player who was actually best while playing within it. Later, I repeated the analysis with stricter requirements. That sensitivity test would prove unusually important. The offensive portion of the study used the same Model C framework developed in my earlier positional analyses.

Each season was evaluated relative to the other second basemen playing during that season. That distinction is essential.

A second baseman from 1991 should not be compared directly with a second baseman from 1927 without adjusting for the environment in which each played. Even within a single decade, offensive conditions change. League scoring changes. Home run rates change. Strikeout rates change. The baseball itself seems occasionally to develop opinions.

The solution is to standardize each component within the season and position.

For any metric , the standardized value is:

z_{i,y,m} = \frac{ x_{i,y,m} - \overline{x}_{y,m} }{ s_{y,m} }

Here, zi,y,m  represents player ‘s value for metric in season , while the denominator represents the standard deviation among the relevant peer group. The result tells us how far above or below the typical second baseman a player performed.

Measuring Offense

The offensive model combines seven dimensions.

\begin{aligned} \mathrm{OffensiveScore} &= z_{\mathrm{OBP}} + z_{\mathrm{ISO}} + z_{\mathrm{BB/PA}} + z_{\mathrm{LowSO/PA}} \\ &\quad + z_{\mathrm{NetSB/PA}} + z_{\mathrm{R/PA}} + z_{\mathrm{RBI/PA}} \end{aligned}

Each term captures something slightly different. On-base percentage rewards the ability to avoid outs. Isolated power separates extra-base power from batting average. Walk rate captures patience. Low strikeout rate rewards contact. Net stolen bases introduce baserunning efficiency. Runs and RBI provide two imperfect but still useful measures of offensive production.

None is sufficient by itself. Together, they form a broader picture of offensive contribution. This is critical especially at second base because the position featured very different offensive styles during the 1990s. Biggio and Knoblauch created value differently from Sandberg. Whitaker’s game was different again. Carlos Baerga produced in a manner that looked much more like a traditional middle-of-the-order hitter.

The model lets us compare those different paths within a common framework.

Measuring Defense

Defense is more difficult. The Lahman database gives us traditional fielding statistics, but it cannot tell us exactly where a defender started, how far he traveled, how difficult the batted ball was, or how many plays another second baseman might have reached.

We do not have Statcast for 1993. Pretending otherwise would make the analysis look more precise while actually making it less honest. Instead, I used the same traditional defensive framework employed in the earlier positional studies.

\mathrm{TraditionalDefensiveScore} = z_{\mathrm{A/G}} + z_{\mathrm{PO/G}} + z_{\mathrm{DP/G}} + z_{\mathrm{FPct}} + z_{\mathrm{LowE/G}}

The model incorporates assists per game, putouts per game, double plays per game, fielding percentage, and a reverse-coded errors-per-game measure. For second basemen, these statistics have some intuitive appeal. Assists reflect involvement in ground-ball plays. Putouts capture participation around the bag. Double plays are especially relevant at a middle-infield position.

Still, the score should not be interpreted as a substitute for modern defensive runs saved; it is better described as a reconstruction of traditional defensive performance.

Combining the Two Sides

Once offensive and defensive career scores were calculated, each dimension was standardized across the qualifying second basemen.

The two-way score was then defined as:

\mathrm{TwoWayScore}_{i} = z_{\mathrm{Offense},i} + z_{\mathrm{Defense},i}

This creates a simple but useful balance. A player cannot dominate merely by hitting if his defense is far below his peers. Likewise, an extraordinary defender must produce enough offensively to remain competitive with more complete players.

That is exactly what we want from a study of second basemen. The position demands both.

The Ranking

The first figure shows the result.
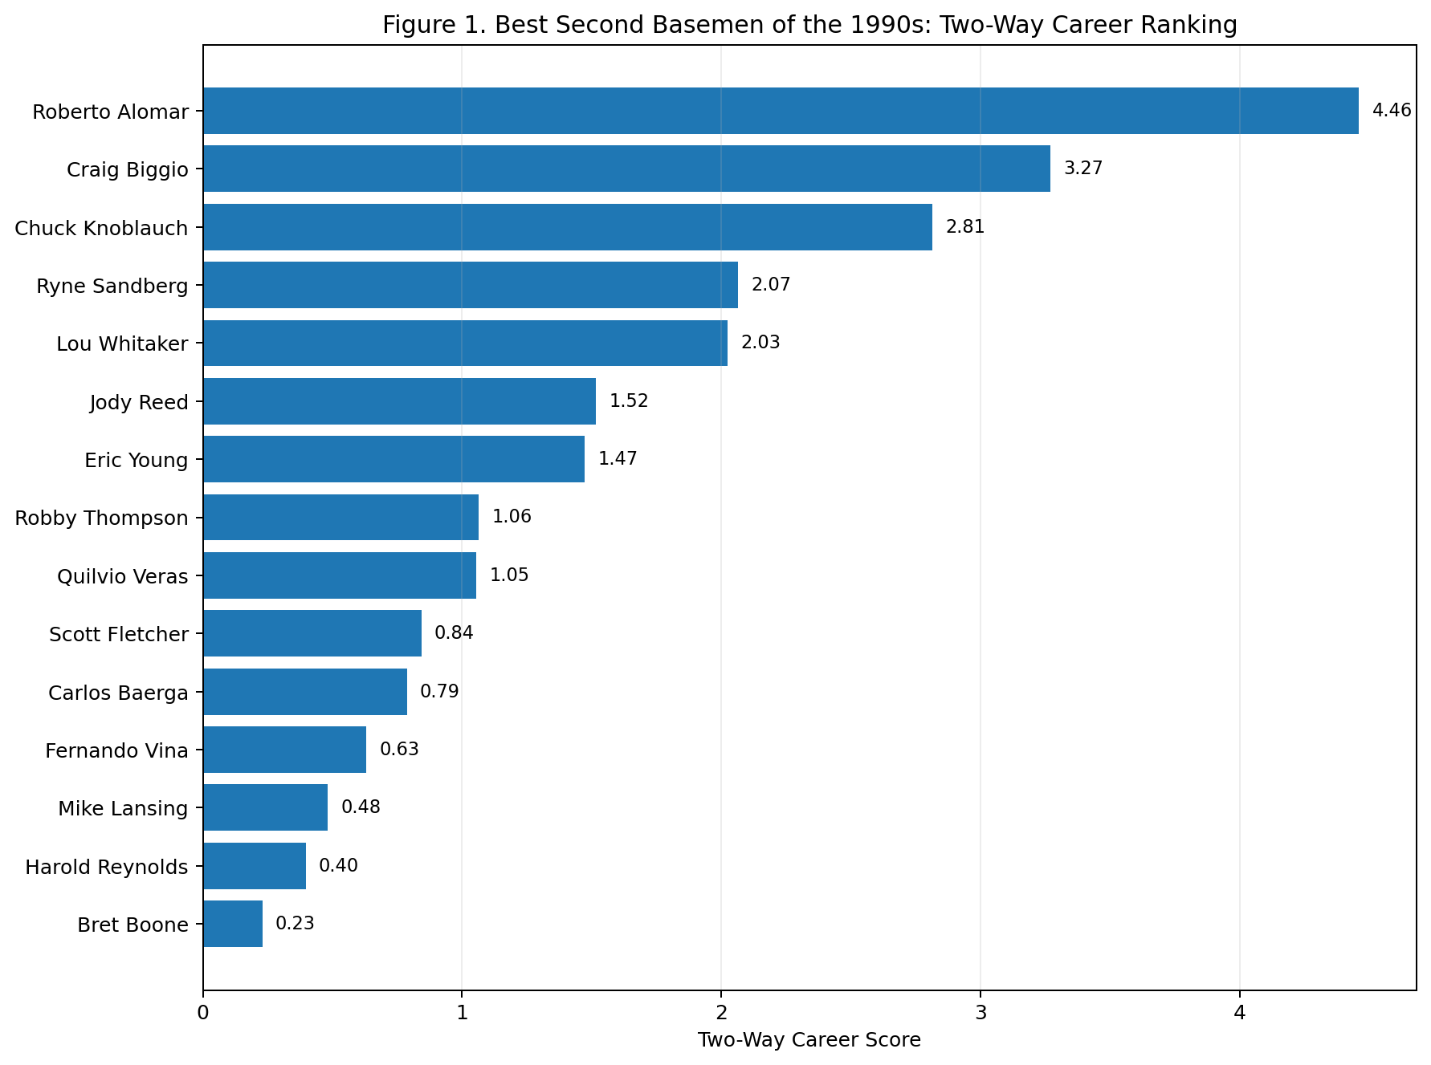
Figure 1. Best Second Basemen of the 1990s: Two-Way Career Ranking.

Roberto Alomar finishes first by a substantial margin. His two-way score is approximately 4.46. Craig Biggio follows at about 3.27, with Chuck Knoblauch third at approximately 2.81.

That is meaningful separation.

The top of the ranking is:

  1. Roberto Alomar
  2. Craig Biggio
  3. Chuck Knoblauch
  4. Ryne Sandberg
  5. Lou Whitaker
  6. Jody Reed
  7. Eric Young
  8. Robby Thompson
  9. Quilvio Veras
  10. Scott Fletcher

The identities are interesting enough. The underlying structure is more revealing. Alomar ranks first offensively and fifth defensively. And when we measure the best three-season peak rather than decade-long accumulation, he ranks first again.

No category defines his candidacy. He scores well everywhere.

Roberto Alomar and the Problem of Completeness

Historical ranking exercises tempt us to assume reputation produced the famous answer. That is not what happened here. The awards were excluded from the calculation.

Gold Gloves did not contribute a single point to Alomar’s defensive score. All-Star selections did not improve his offensive ranking. Hall of Fame status was irrelevant. Only after the rankings were complete did I return to the historical record. The agreement was striking.

Alomar made ten All-Star teams during the 1990s and won eight Gold Gloves. He also won three Silver Sluggers. Those honors are not proof that the model is correct. Awards contain their own biases and imperfections.

But they are useful independent evidence. A statistical model constructed without reference to contemporary voting concludes that Alomar was the best all-around second baseman of the decade. The people watching baseball during the decade repeatedly reached a similar conclusion.

Different Roads to Value

A single ranking can hide the most interesting part of the story. To see the players more clearly, we can separate offense and defense.
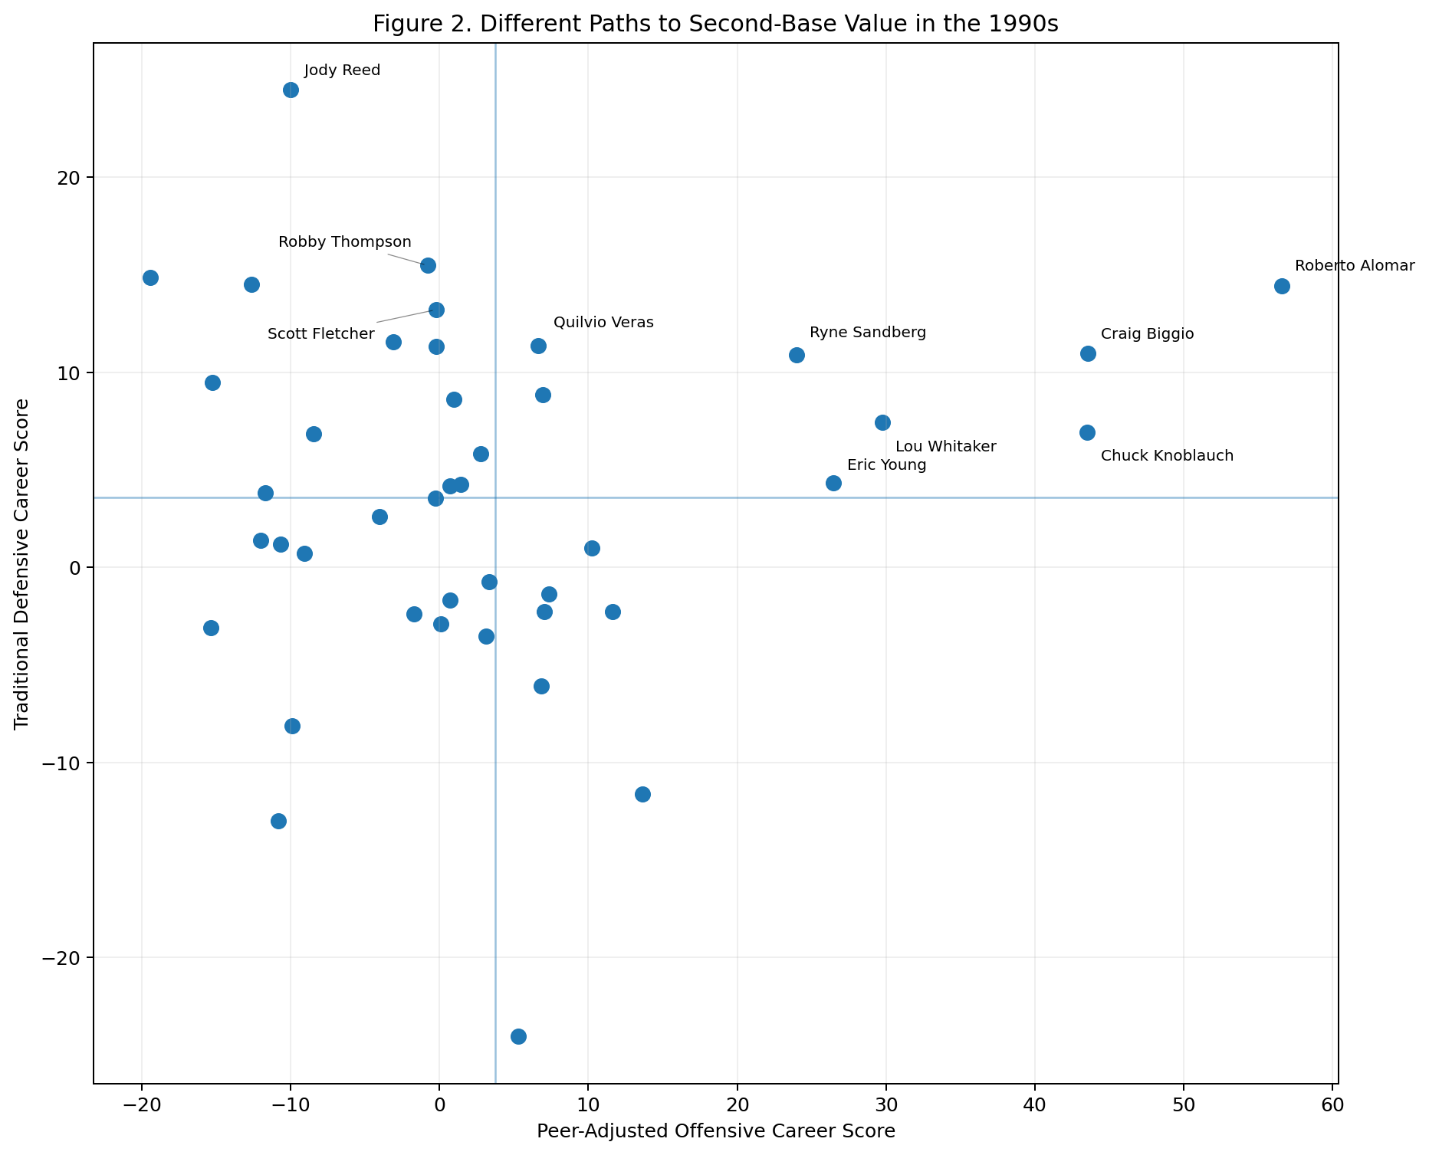
Figure 2. Different Paths to Second-Base Value in the 1990s.

The horizontal axis represents peer-adjusted offensive performance. The vertical axis represents traditional defensive performance. Now the decade stops looking like a list and begins looking like a landscape.

Alomar occupies the desirable region in which strong offense and strong defense coexist. He is not merely the player with the largest total score. He is positioned where we would intuitively expect a great all-around second baseman to appear.

Biggio and Knoblauch move further toward the offensive side. Jody Reed and Robby Thompson move sharply toward the defensive side.

Sandberg occupies a more balanced region. Lou Whitaker also remains strong offensively despite being near the end of his career. Several different kinds of second basemen are visible at once.

This is why I prefer the scatterplot to the ranking alone. A ranking tells us who accumulated the most modeled value. The scatterplot tells us how.

Biggio and Knoblauch

One of the study’s most remarkable numerical results involves Craig Biggio and Chuck Knoblauch. Surprisingly, their offensive decade scores are nearly identical.

Biggio’s score is approximately:

\mathrm{OffensiveScore}_{\mathrm{Biggio}} = 43.546

Knoblauch’s is approximately:

\mathrm{OffensiveScore}_{\mathrm{Knoblauch}} = 43.520

The difference is almost trivial. That is intriguing because memory tends to organize careers into larger categories. Biggio became a Hall of Famer and accumulated more than 3,000 hits. Knoblauch’s career eventually became associated with his move to the Yankees and later throwing problems.

But if we isolate the 1990s and examine their offensive performance at second base, they were extraordinarily close. The separation comes primarily from defense.

Biggio ranks tenth in the traditional defensive model. Knoblauch ranks sixteenth. That difference is enough to move Biggio into second place overall and leave Knoblauch third.

This is a good example of why career reputation can distort a decade-specific study. We are not ranking Biggio and Knoblauch’s total careers. We are only ranking what they did during these ten seasons.

Ryne Sandberg and the Shape of a Declining Career

Sandberg finishes fourth overall. That ranking deserves some context.

His greatest seasons began before the decade started. By 1990, he was already an established star and a former MVP. He also retired temporarily after the 1994 season before returning in 1996.

A decade-total calculation therefore places him at an obvious disadvantage against players whose prime years fall almost perfectly within the 1990s.

Peak analysis changes the picture. Sandberg ranks third in three-season peak. That is much closer to how his best baseball felt. At his highest level during the decade, he remained one of the most dominant second basemen in the game. The career total is lower because the decade captures only part of his greatness.

That distinction between accumulated value and concentrated excellence is one of the reasons I wanted to calculate both.

Lou Whitaker and the Vanishing Star

Lou Whitaker may be the most interesting player in the entire study. He finishes fifth overall, but in the three-season peak calculation, he rises to second.

Only Roberto Alomar is higher. That result deserves attention because Whitaker was already nearing the end of his career when the decade began. He had been Detroit’s second baseman since the late 1970s, and his partnership with Alan Trammell had defined the Tigers’ middle infield for years.

Yet his late-career production remained remarkably strong. Whitaker ranks fourth offensively in the 1990s study despite having only five qualifying offensive seasons during the decade.

And then we reach the strange part. He made zero All-Star teams during the 1990s. The model sees an elite late-career second baseman.

Contemporary All-Star voting during that same period largely stopped seeing him. There are several possible reasons. Whitaker was aging. Detroit was no longer the dominant club it had been in 1984. New stars such as Alomar and Knoblauch had arrived.

Recognition sometimes tends to move toward the new. Whitaker’s result is a reminder that reputation is not simply a measure of production. It is also influenced by timing, novelty, team success, narrative, and the human tendency to move on. The numbers sometimes remember players longer than the audience does.

Career and Peak

The relationship between career value and peak value is shown in Figure 3.
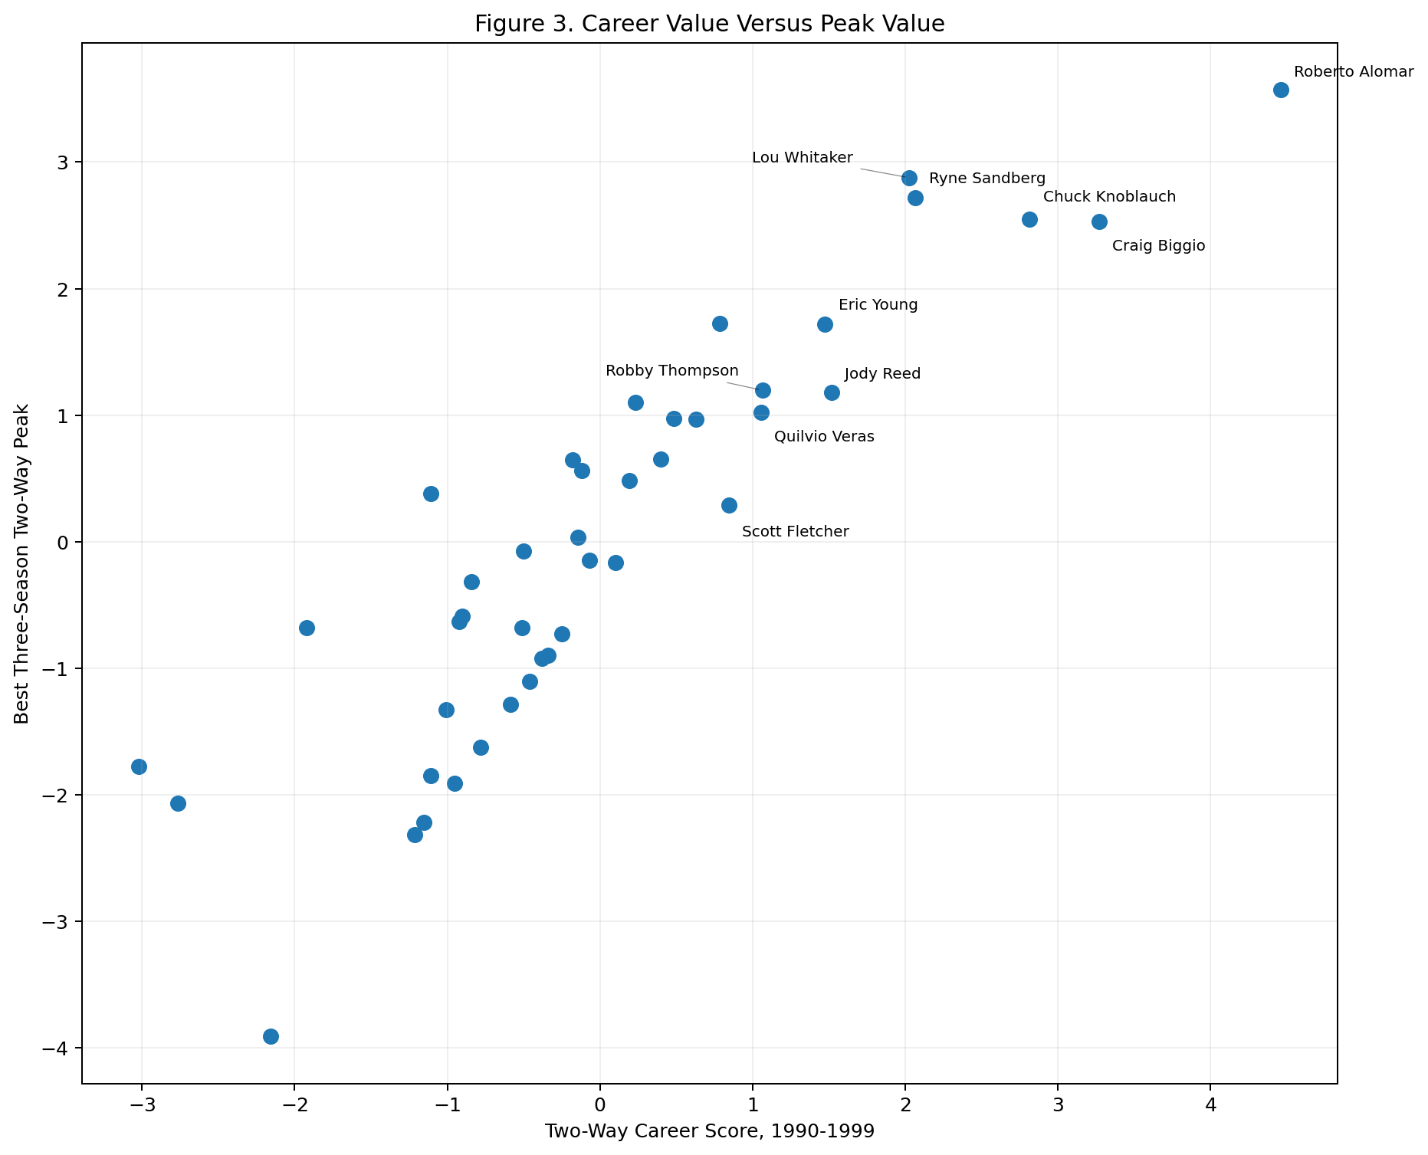
Figure 3. Career Value Versus Peak Value.

Players toward the right accumulated strong decade-long value, whereas players toward the top reached especially strong three-season peaks. The ideal player appears in the upper-right. Once again, Alomar occupies that region.

Biggio’s accumulated value is exceptional, while Sandberg and Whitaker move upward when peak is emphasized. Knoblauch remains strong in both dimensions.

The figure also exposes players whose value was concentrated. Carlos Baerga is a particularly good example. He finishes outside the top ten overall but ranks sixth in peak value. At his best in Cleveland, Baerga was an extraordinary offensive second baseman. He hit for average, produced runs, and occupied an important position in one of the strongest lineups of the decade.

His peak was excellent; I had a front-row seat for it. The decade as a whole was less complete.

Jody Reed: The Defensive Outlier

Then there is Jody Reed. Reed ranks thirty-fourth offensively, but he ranks first defensively. And somehow, when the two dimensions are combined, he finishes sixth overall.

That is such an unusual statistical profile that it deserves examination rather than dismissal. The earlier shortstop study produced something similar with Mark Belanger. Belanger’s offense was weak, but his defense was so exceptional that the combined model still valued him highly.

Reed becomes the second-base version of that problem. Traditional fielding statistics love him. He accumulated assists. He participated in double plays. He avoided errors at a high rate. Across the available measures, he repeatedly performed well relative to other second basemen.

Does that mean Jody Reed was literally the best defensive second baseman of the 1990s?

I would not make that claim. The model cannot measure positioning, range in modern terms, or opportunity quality. It cannot tell us whether two second basemen facing identical batted balls would have produced identical results. What it can tell us is that Reed’s surviving traditional defensive record is unusually strong.

Jeff Kent and the Danger of Career Memory

Jeff Kent creates the opposite kind of problem. When we hear the phrase “great second baseman,” Kent belongs in the conversation. He eventually won an MVP award and became one of the greatest power-hitting second basemen in baseball history.

Yet he finishes only twenty-first in this study. At first, that feels wrong until we remember the question. This is not a career ranking. Kent did not reach the height of his offensive career until the end of the 1990s and into the early 2000s. His MVP season came in 2000, immediately outside our study window.

Inside the 1990s alone, he ranks eighth offensively but much lower defensively. The combined result therefore pushes him down.

There is no contradiction. Kent’s career was greater than his 1990s ranking because much of that greatness came after the decade ended. Artificial boundaries create artificial problems, but they also allow us to ask very specific questions.

Similar Players, Different Players

Rankings impose order while clustering reveals resemblance. For the final figure, I took the top fifteen second basemen and compared them using standardized offense, defense, and three-season peak. A hierarchical clustering algorithm then grouped players according to similarity.
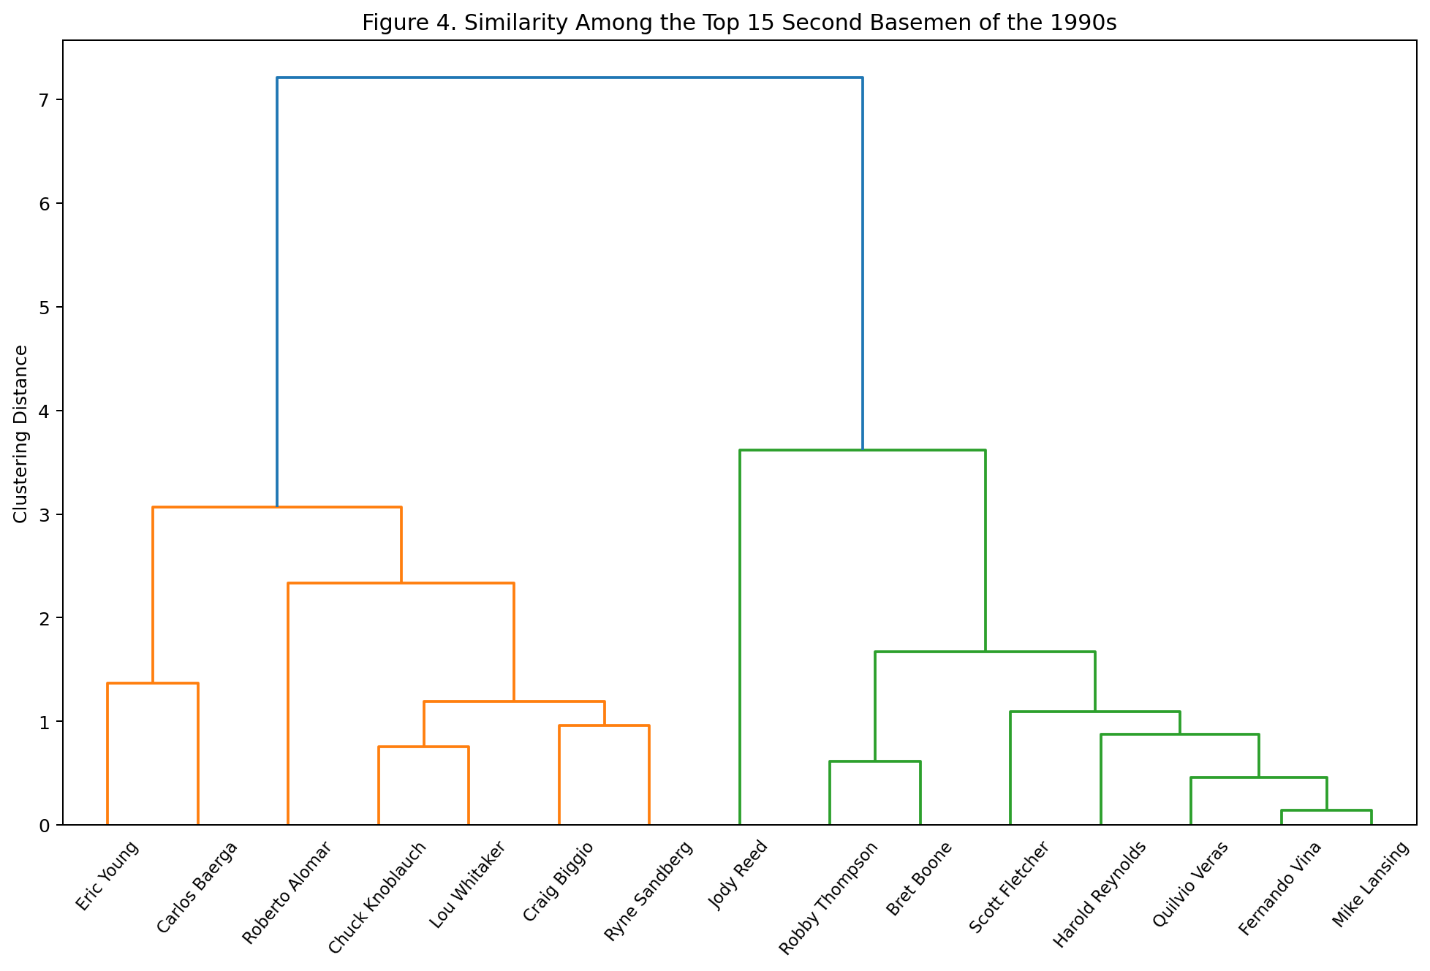
Figure 4. Similarity Among the Top 15 Second Basemen of the 1990s.

The dendrogram separates players who may sit near one another in the ranking but arrived there by very different routes. Alomar belongs naturally near the strong offensive players, but his defensive performance keeps him from looking like a pure bat-first second baseman.

Biggio, Knoblauch, Whitaker, Sandberg, Baerga, and Eric Young occupy a broadly offense-oriented portion of the tree, whereas Reed and Robby Thompson pull toward the defense-heavy side.

The point is not that one branch is better than another. The ranking already addresses that question.

The dendrogram asks something else: What kind of second baseman was he? That is often the more interesting historical question.

Testing the Result

A good ranking should not collapse when one arbitrary assumption changes. So I changed several. First, I increased the minimum qualification requirement from three seasons to five. Then I imposed a minimum number of games at second base.

I tested a 400-game threshold, tightening the combination further. Finally, I removed the playing-time weighting from the seasonal calculations.

Every major version produced the same top five in precisely the same order:

  1. Roberto Alomar
  2. Craig Biggio
  3. Chuck Knoblauch
  4. Ryne Sandberg
  5. Lou Whitaker

That is unusually strong stability.

If Biggio had jumped ahead of Alomar whenever the threshold changed slightly, we would have reason to hesitate. He did not. If Sandberg disappeared when playing-time requirements changed, his placement would be suspicious. He also did not.

The model is telling us something persistent rather than something dependent on a convenient cutoff.

The Limits of the Exercise

No mathematical ranking resolves baseball history. A model is an argument expressed numerically. The variables I choose reflect what I think matters. The weights reflect judgments, even when those weights are equal. The available data determine which questions can be answered and which must remain uncertain.

Traditional defensive data are particularly limiting. Our model cannot know how many steps Alomar moved to his left before making a play. It cannot reconstruct every double-play opportunity Jody Reed received. It cannot distinguish perfectly between range and positioning.

Nor can offensive statistics capture every element of game context. The value of the model is not that it replaces baseball judgment. The value is that it forces the judgment to confront evidence.

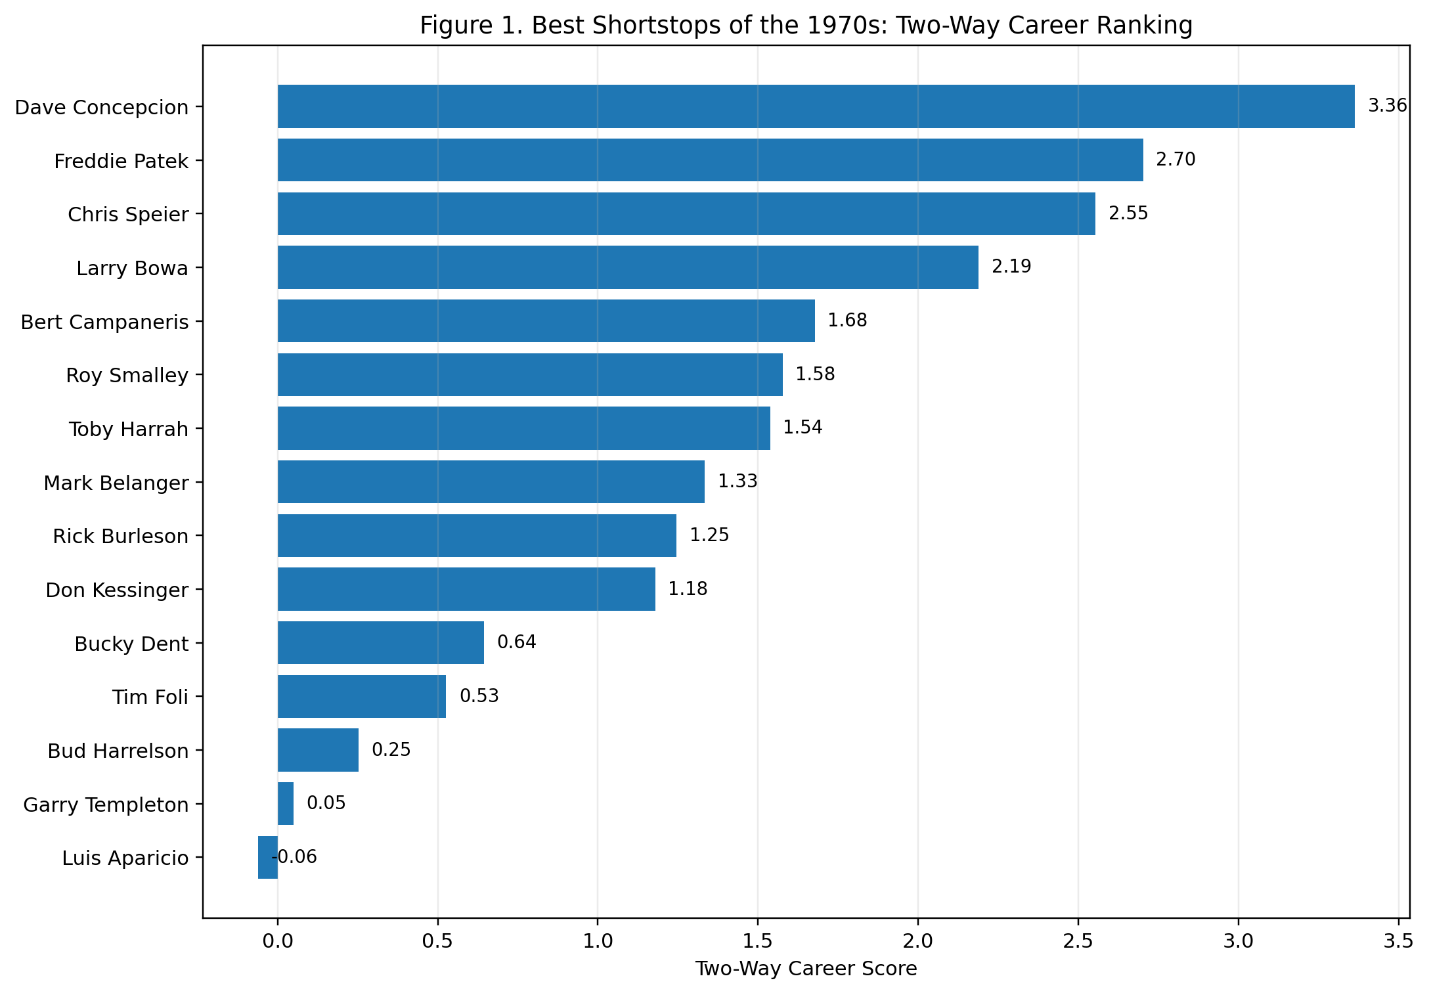
Sometimes the evidence confirms what we thought. Sometimes it produces Freddie Patek, Sometimes it produces Jody Reed. And sometimes it reminds us that Lou Whitaker was still very good after much of baseball had apparently stopped paying attention.

The Best Second Baseman of the 1990s

In the end, Roberto Alomar is the easiest conclusion in the study. He ranks first offensively. He ranks fifth defensively. He ranks first in three-season peak and first in total two-way value.

The result survives stricter qualification rules, minimum-game requirements, and changes in weighting. The awards agree with the statistical evidence without having influenced it. Alomar was simply the most complete second baseman of the decade.

The more interesting story begins beneath him. Craig Biggio and Chuck Knoblauch produced almost identical offensive value, yet Biggio’s stronger traditional defense separates them. Ryne Sandberg remained capable of extraordinary peak performance even as the decade captured only the latter portion of his greatness. Lou Whitaker quietly produced one of the strongest peaks in the study while receiving almost no All-Star recognition.

Jody Reed reminds us that defense can create strange statistical profiles. Carlos Baerga reminds us that peak and longevity are different forms of greatness. Jeff Kent reminds us that a decade boundary can divide a career at exactly the wrong place. Together, they reveal something broader about second base. There was no single way to play it well.

The 1990s produced leadoff hitters, power hitters, contact hitters, base stealers, defensive specialists, fading veterans, and emerging stars. They did not occupy a neat continuum from bad to good. They occupied a landscape whose highest point was Roberto Alomar. Not because we remembered him that way, but because, after taking the memory away and letting the data speak first, he ended up there.
 

The Thief Who Stole Only the Peel

The Thief Who Stole Only the Peel: How a seemingly modest agreement can cost you almost an entire orange

A thief approaches an orange merchant (what?) with an unusual proposal. He wants to take an orange, but promises to leave its interior untouched. Is he drunk or otherwise impaired? Is he, perhaps, some sort of citrus provocateur?

He wants only the peel. More precisely, he wants the outer layer extending inward through one-tenth of the orange’s radius.

The merchant considers the offer. If the orange has a radius of ten centimeters, the thief will remove a one-centimeter-thick layer, leaving a ball with a radius of nine centimeters.

That sounds like a substantial peel, but an acceptable bargain. The merchant agrees, assuming that most of the orange will remain on the counter.

For an ordinary orange, he is right. Unfortunately, the thief has selected an orange with one hundred dimensions.

The first orange

Before considering the merchant’s unfortunate predicament, let us examine an ordinary three-dimensional orange. We will treat it as a perfect sphere with uniform density, and “peel” will mean the specified outer layer rather than its actual skin.

The volume of a sphere is proportional to the cube of its radius. If we reduce its radius to 90 percent of the original, we retain 90 percent × 90 percent × 90 percent of its volume.

The fraction remaining is therefore: (0.9)3 = 0.729

The merchant keeps 72.9 percent of the orange, and the thief receives 27.1 percent. A layer occupying only one-tenth of the radius has taken more than a quarter of the volume.

That result already deserves a moment’s attention. A percentage of the radius is not the same thing as a percentage of the volume, because volume depends on three dimensions working together.

The merchant may have underestimated the thief’s breakfast. Nevertheless, he still has most of his orange.

An orange we cannot picture

A hundred-dimensional orange is difficult to imagine, which is a polite way of saying that I cannot picture one. Fortunately, you don’t need to picture an object to define it mathematically.

On a flat surface, a disk consists of all points within a specified distance of a center. In three dimensions, the corresponding solid object is a ball, with each point located by three coordinates.

We can extend that definition to one hundred coordinates. A hundred-dimensional ball consists of all points whose Euclidean distance from its center is no greater than its radius.

These dimensions do not have to represent additional directions we could physically walk. In data analysis, coordinates can represent measured variables, although the choice of units and scaling then matters.

We can study this ball’s volume even when our visual imagination has stopped cooperating. The key is that its volume scales with its radius raised to the number of dimensions.

In three dimensions, the power is three. In one hundred dimensions, the power is one hundred.

The same agreement, a different breakfast

The thief’s agreement remains unchanged. He takes the outermost tenth of the radius, leaving an inner ball with 90 percent of the original radius.

For a ball with dimensions, the fraction of the volume left inside is: (0.9)n

The fraction taken by the thief is whatever remains after subtracting that quantity from one. We can therefore write: 1-(0.9)n

There is a constant in the full formula for the volume of a ball, and that constant changes with the number of dimensions. Here it cancels, because we are comparing two balls in the same number of dimensions.

The results make the thief’s interest in unusual produce easier to understand. Each row applies to the same agreement.

Dimensions Merchant keeps Thief takes
2 81.000% 19.000%
3 72.900% 27.100%
10 34.868% 65.132%
20 12.158% 87.842%
50 0.515% 99.485%
100 0.002656% 99.997344%

In ten dimensions, the merchant has already lost nearly two-thirds of the orange. In fifty dimensions, he keeps approximately half of one percent.

At one hundred dimensions, the calculation becomes: (0.9)100 ≈ 0.00002656

That is a fraction, so we multiply by one hundred to express it as a percentage. The merchant retains approximately 0.002656 percent of the original volume.

The thief receives approximately 99.997344 percent. He has taken almost the entire orange while honoring every word of the agreement.

Where did the interior go?

The natural temptation is to imagine that something has pushed the orange’s contents outward. Perhaps the center has become hollow, or the fruit has accumulated against its skin.

Neither has happened in our mathematical model. The ball is uniformly filled, and the amount of material per unit of volume is the same throughout.

The central region still exists. It simply accounts for an extraordinarily small fraction of the total volume.

The arithmetic explains why. Every increase in dimension adds another factor of 0.9 to the fraction the merchant keeps, and repeated multiplication by a number smaller than one steadily reduces the result.

Our everyday experience gives us little reason to expect such a dramatic reduction. We live in three spatial dimensions, where keeping nine-tenths of the radius still leaves nearly three-quarters of the volume.

In one hundred dimensions, the same proportional reduction leaves almost nothing by comparison. Our familiar intuition carries over into a setting where it no longer provides a reliable estimate.

Choose a point anywhere

Another way to understand the result is to imagine selecting points uniformly at random throughout the hundred-dimensional orange. “Uniformly” means that regions with equal volume have equal chances of receiving a selected point.

Approximately 99.997 percent of those points will fall in the outermost tenth of the radius. If we select one hundred thousand points, the expected number in the inner ball is only about 2.7.

This does not mean that every sample will leave exactly two or three points inside. It means that, over repeated samples, the average count there would be approximately 2.7.

The points have no preference for the edge. The outer layer receives almost all of them because it contains almost all the available volume.

There is also a distinction between being near the surface and being on it. The mathematical surface has zero volume, so a uniformly selected point has probability zero of landing exactly there, even though landing nearby is overwhelmingly likely.

Why this matters beyond imaginary fruit

A dataset with many measured variables can be represented as a collection of points in a space with many coordinates. A baseball player, for example, might be described by on-base percentage, isolated power, strikeout rate, walk rate, sprint speed, and numerous other measurements.

Add enough variables, and the number of dimensions quickly exceeds anything we can visualize. We may still describe observations as “close,” “central,” or “far away,” but those descriptions now depend on geometry that can behave quite differently from the geometry of a baseball field.

Real datasets do not automatically behave like points distributed uniformly inside a ball. Variables may be correlated, observations may cluster, and changing a measurement’s scale can change the distances between points.

The orange therefore teaches us about our expectations, rather than providing a universal description of data. It shows how a familiar geometric judgment can become unreliable when the number of dimensions changes.

Methods such as principal component analysis help us investigate structure in data with many variables. They can also give us a lower-dimensional view, although that view necessarily leaves out some information unless the data already lie within the retained dimensions.

There is a useful discipline here. Before trusting a picture formed in three-dimensional experience, we should ask whether the mathematics supports carrying that picture into a space with fifty or one hundred dimensions.

Reading the agreement

The merchant understood that the thief would remove a layer one-tenth of the radius thick. His mistake was assuming that this measurement told him, intuitively, how much orange he would surrender.

In three dimensions, that assumption was imperfect but survivable. In one hundred dimensions, it cost him almost everything.

In this world, the thief leaves with his peel, and the merchant is left studying a very small remainder. Word on the street is that next time, he plans to negotiate in percentages of volume.


The Distribution Was There All Along: Why Scale Matters in Stem-and-Leaf Plots

The Distribution Was There All Along: Why Scale Matters in Stem-and-Leaf Plots

Author’s Note: Are there any aspiring scientists reading this post? If so, pay attention to what you are about to read. I always start any serious study with stem-and-leaf plots, and you should, too. Read on and find out why. And yes, archaeologists work in meters, but most people who read my blog are from the USA, so I will use the imperial system. That said, I want to recognize the growing number of Chinese readers clicking on my site; I see you, and I deeply appreciate that you are here. Let’s begin…

When I taught archaeology in an anthropology department at a Midwestern university about a million years ago, I sometimes started class with a simple exercise. I asked the students to write down their heights.

No archaeological theory. No artifacts. No radiocarbon dates. Just height. Then we put the observations together and constructed a stem-and-leaf plot.

The exercise had a larger purpose. Human height data can contain more than one concentration, especially when a classroom contains individuals drawn from populations with different average heights. If those concentrations are sufficiently separated, the resulting distribution can be bimodal. But that exercise hides another lesson, and it is an important one. Whether we see bimodality depends on how we construct the stem-and-leaf plot.

A Synthetic Classroom

To demonstrate the idea clearly, I created a synthetic dataset containing 200 student heights. I generated the observations from two overlapping height distributions, with 100 observations in each group. The first is concentrated around approximately 64 inches, and the second around approximately 71 inches.

The combined dataset has an overall mean of:

67.44 inches

and a median of:

67.00 inches

Those numbers are mathematically correct. But they do not tell us the most interesting thing about the data.

There are two concentrations. That distinction is critical because a measure of central tendency answers a particular question: where is the center of the combined data?

It does not necessarily answer another question: what does the distribution actually look like?

Those are not always the same problem.

Start With a Coarse Stem

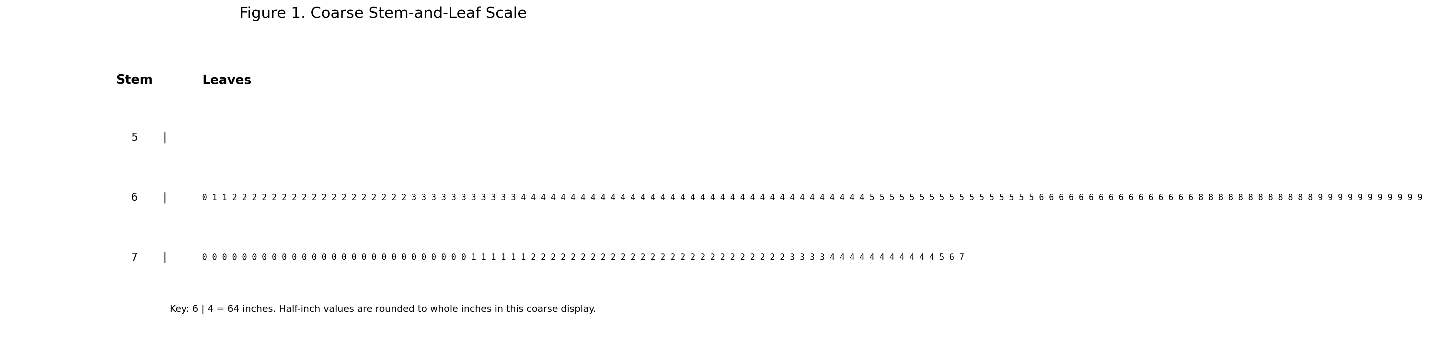
Suppose we begin with a conventional-looking stem-and-leaf plot in which the tens digit serves as the stem.

A height of 64 inches would therefore appear as:

6 | 4

A height of 71 inches would appear as:

7 | 1

That seems reasonable enough.

Figure 1. The 200 synthetic heights displayed using a coarse stem-and-leaf scale.

The problem becomes apparent almost immediately. There are only a few stems, and an enormous number of leaves are crowded onto them. The individual observations are technically still present, but the visual structure of the distribution has been compressed.

The plot contains the information; it just doesn’t display it effectively. This is an important distinction. A graph can be numerically correct while still being visually uninformative.

Change the Scale

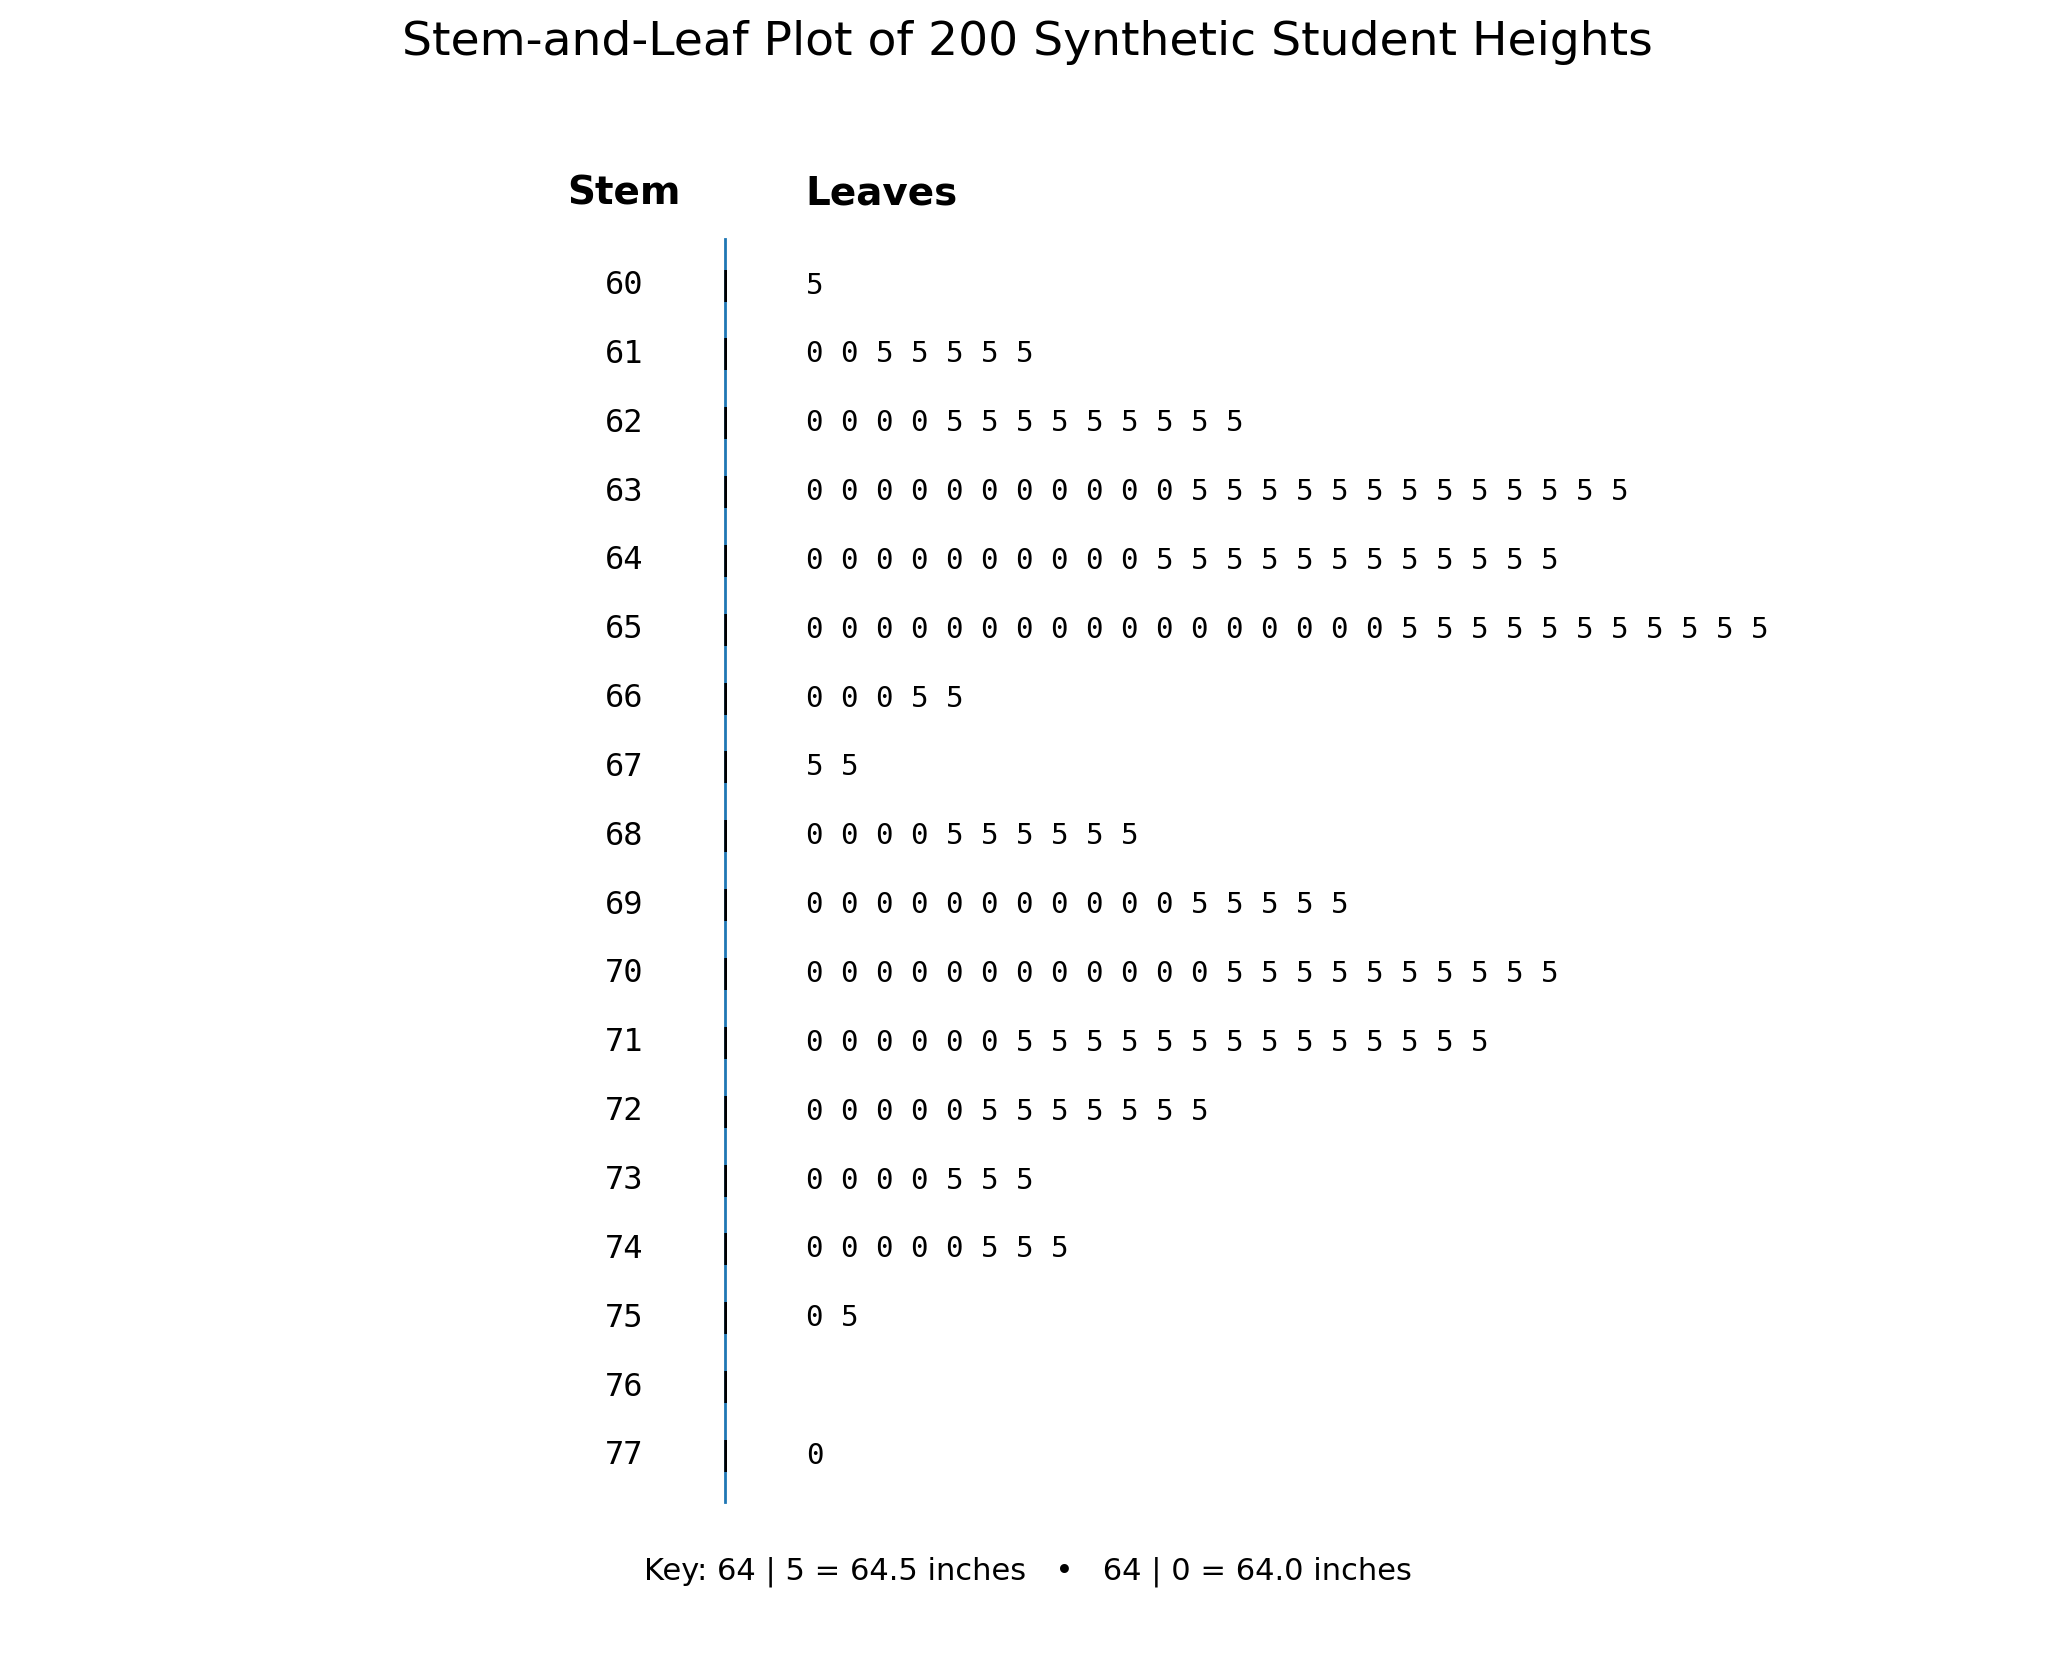
Now consider exactly the same dataset with a different stem-and-leaf scale. Instead of using the tens digit as the stem, let each whole inch become a stem. Because our measurements were recorded to the nearest half-inch, we can use two possible leaves:

0 for a whole inch

and

5 for a half inch.

Thus,

64 | 0

represents 64.0 inches, while

64 | 5

represents 64.5 inches.

Nothing about the underlying dataset has changed; only the scale has changed.

Figure 2. The same 200 synthetic heights using whole inches as stems and half inches as leaves.

The distribution is much easier to interpret now. The observations are no longer compressed into only a handful of rows. Instead, the frequencies expand vertically across the range of heights.

The two concentrations become visible. One cluster occurs in the lower-to-mid 60s. Another occurs around the low 70s. Between them is a region with fewer observations.

That valley is the clue. We are looking at a bimodal distribution.

Same Data, Different Picture

This is what makes the example useful. Figure 1 and Figure 2 contain essentially the same information. The difference is not the sample. It is not the statistical method. It is not the population. The difference is scale.

A stem-and-leaf plot has a built-in parameter that we sometimes treat as mere formatting. It is not.

The choice of stem width determines how much of the distribution’s internal structure we can see.

Use stems that are too broad and separate features may be compressed together.

Use stems that are too narrow, and the opposite problem can occur. The distribution may become excessively sparse, with random sampling variation producing a jagged pattern that looks more meaningful than it really is.

Therefore, no stem width is universally correct.

Scale must fit the data.

Check It With a Histogram

We can verify what the finer stem-and-leaf plot is showing by constructing a histogram of the same 200 observations.

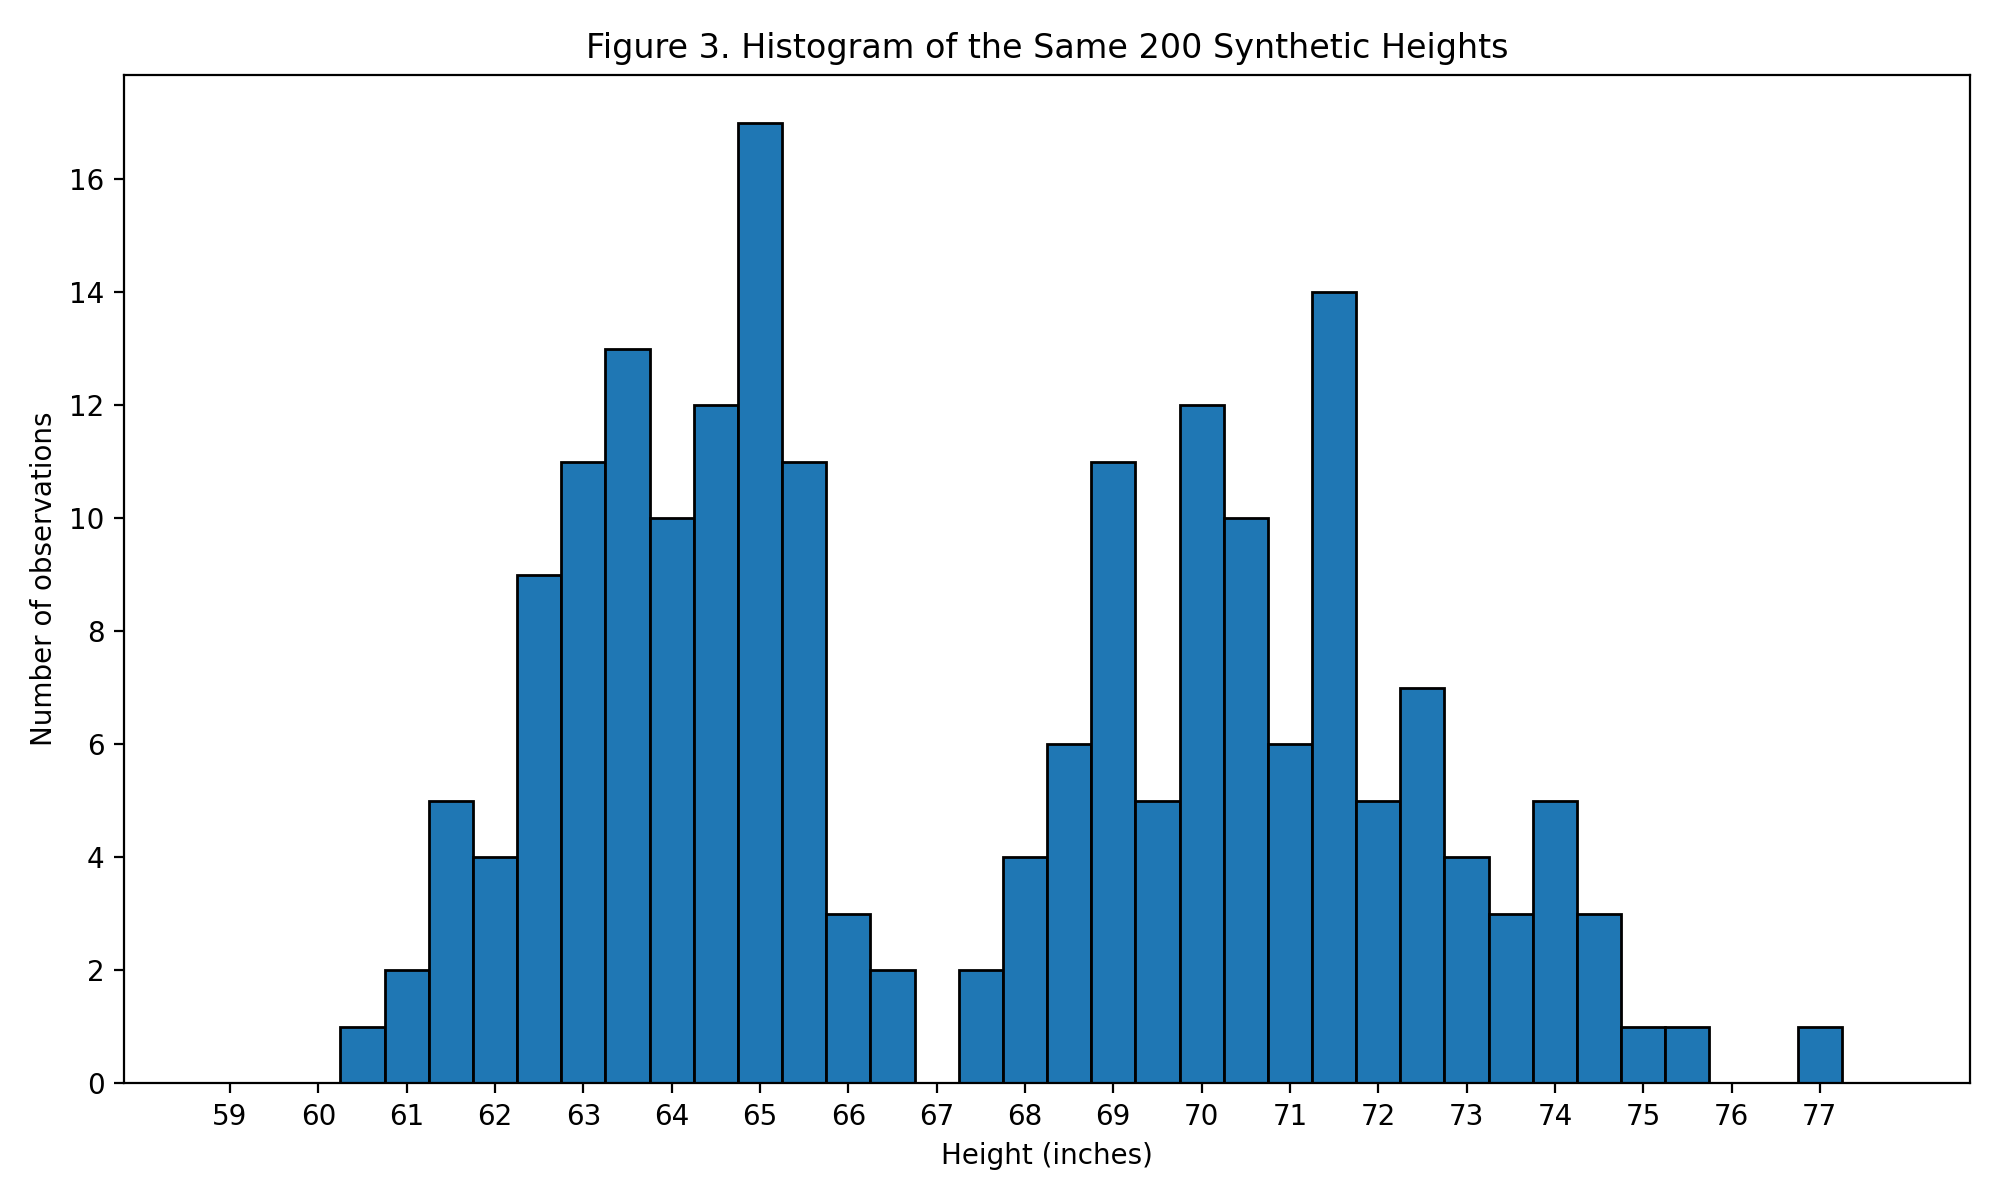
Figure 3. Histogram of the same synthetic height data.

The histogram confirms the pattern. A lower-frequency region separates two relatively high-frequency regions. The distribution doesn’t behave like one simple mound centered around 67 inches.

That makes the overall mean of 67.44 inches especially interesting. The mean is not wrong. It answers a question that may not be the one we actually care about.

If the underlying dataset represents a mixture of two populations, the combined mean can fall in a location that isn’t particularly representative of either population.

This is one reason exploratory data analysis should generally come before aggressive numerical summarization. Right? Do you see it?

The Average Can Hide the Population

Suppose someone gave us only these statistics:

Statistic Value
Sample size 200
Mean height 67.44 in.
Median height 67.00 in.

Nothing looks obviously suspicious. We might reasonably imagine a single distribution centered somewhere around 67 inches. But that interpretation would be incomplete.

The graphical analysis tells us something the mean and median cannot: the observations appear to be concentrated around two different regions. This does not mean you can’t calculate measures of central tendency for bimodal data. They certainly can.

It means a single measure of central tendency may poorly describe a multimodal distribution. That is a much more important lesson.

Why Stem-and-Leaf Plots Are Still Relevant

Histograms are excellent for examining distributions, but stem-and-leaf plots have an easy-to-overlook advantage. They preserve the observations.

A histogram converts individual measurements into frequencies inside bins. Once we see a bar containing 18 observations, we know there are 18 observations in that interval, but we no longer see each value.

A stem-and-leaf plot provides both. We see the shape of the distribution while retaining the underlying measurements.

That makes the technique particularly useful for small and moderate-sized datasets, classroom demonstrations, exploratory analysis, and situations in which we want students to understand that a distribution is constructed from actual observations.

It also makes scale unusually important. Changing a histogram’s bin width can dramatically change its appearance. Changing the stem definition in a stem-and-leaf plot can do the same thing. The underlying principle is identical.

A General Rule for Exploratory Data Analysis

This broader lesson goes beyond stem-and-leaf plots. Whenever we visualize quantitative data, we make resolution decisions. Histogram bin width is a decision. The bandwidth of a density curve is a decision. The limits of an axis are decisions. The size of groups in an aggregated table is a decision. And the scale of a stem-and-leaf plot is a decision.

Those choices influence what patterns become visible. That does not mean we should manipulate scales until we find the pattern we want. Quite the opposite. It means we should examine a dataset at several reasonable resolutions and ask whether an apparent feature persists.

If a second mode appears only under one bizarre choice of scale, we should be skeptical. If the same structure appears across several sensible scales and is confirmed by another visualization, such as a histogram, then the evidence becomes considerably stronger.

The Archaeology Connection

This lesson is particularly relevant to archaeology. Imagine measuring projectile points, pottery thickness, vessel diameters, burial depths, artifact weights, settlement sizes, or some other quantitative attribute.

A single sample might actually contain objects from different chronological periods, manufacturing traditions, functional categories, or cultural populations. If those observations are combined, the mean may fall neatly between them.

The arithmetic may be impeccable; the interpretation may be terrible.

A bimodal distribution can therefore be more than an interesting statistical shape. It can be evidence that what we thought was one population may actually contain multiple processes or populations.

That is why the first question should often (always?) be:

What does the distribution look like? Only after that should we become overly interested in what its average happens to be.

The Lesson

The 200 synthetic heights did not become bimodal when we changed the stem-and-leaf scale. They were bimodal before we touched the graph. The finer scale simply allowed us to see what was already there.

That is the lesson I wanted students to encounter when they wrote their heights down in class. Statistics is not merely the calculation of means, medians, standard deviations, and other summary measures. It is the search for structure in data. Sometimes that structure sits right in front of us, waiting for us to choose the right scale.


The Distribution of Offensive Performance in Major League Baseball, 2026

The Distribution of Offensive Performance in Major League Baseball, 2026

A Statistical Examination of Baseball’s Best, Worst, and Most Typical Hitters

I’ve completed an analysis using FanGraphs data, and the results are quite interesting.

The most important initial discovery is that offensive performance among established MLB hitters is remarkably close to a normal distribution. However, that distribution changes substantially depending on the minimum number of plate appearances we recognize.

I created five figures to illustrate the findings.

Establishing our population

The expanded FanGraphs dataset contains 1,472 player records. Of those, 662 recorded at least one plate appearance during the 2026 regular season. For the primary analysis, I selected 250 plate appearances, giving us 318 players. However, I also examined several alternative thresholds.

Minimum PA Players Mean wRC+ Median wRC+ Standard deviation
1 662 81.87 89.74 52.31
100 465 95.17 96.28 26.26
250 318 102.52 101.75 21.46
400 205 108.25 107.01 19.90
502 135 111.29 110.53 19.98

Notice what happens as we increase the minimum playing-time requirement. The mean rises, while the standard deviation generally decreases. This is consistent with two processes operating together: small-sample extremes becoming less influential and better hitters tending to accumulate more plate appearances.

There is an important selection effect here. Players with poor offensive performances are less likely to receive 500 or more plate appearances. Consequently, the average performance of our qualified hitters is considerably better than the MLB-wide benchmark of 100 wRC+.

Is offensive performance normally distributed?

For our primary population of 318 players, the descriptive statistics are:

Statistic wRC+
Mean 102.52
Median 101.75
Standard deviation 21.46
Minimum 32.62
Maximum 180.82
First quartile 89.22
Third quartile 116.23
Interquartile range 27.01
Skewness 0.06
Excess kurtosis 0.25

The mean and median are remarkably close. Furthermore, the skewness of 0.06 suggests that the distribution is approximately symmetrical. The kurtosis is also reasonably close to that expected under a normal distribution.

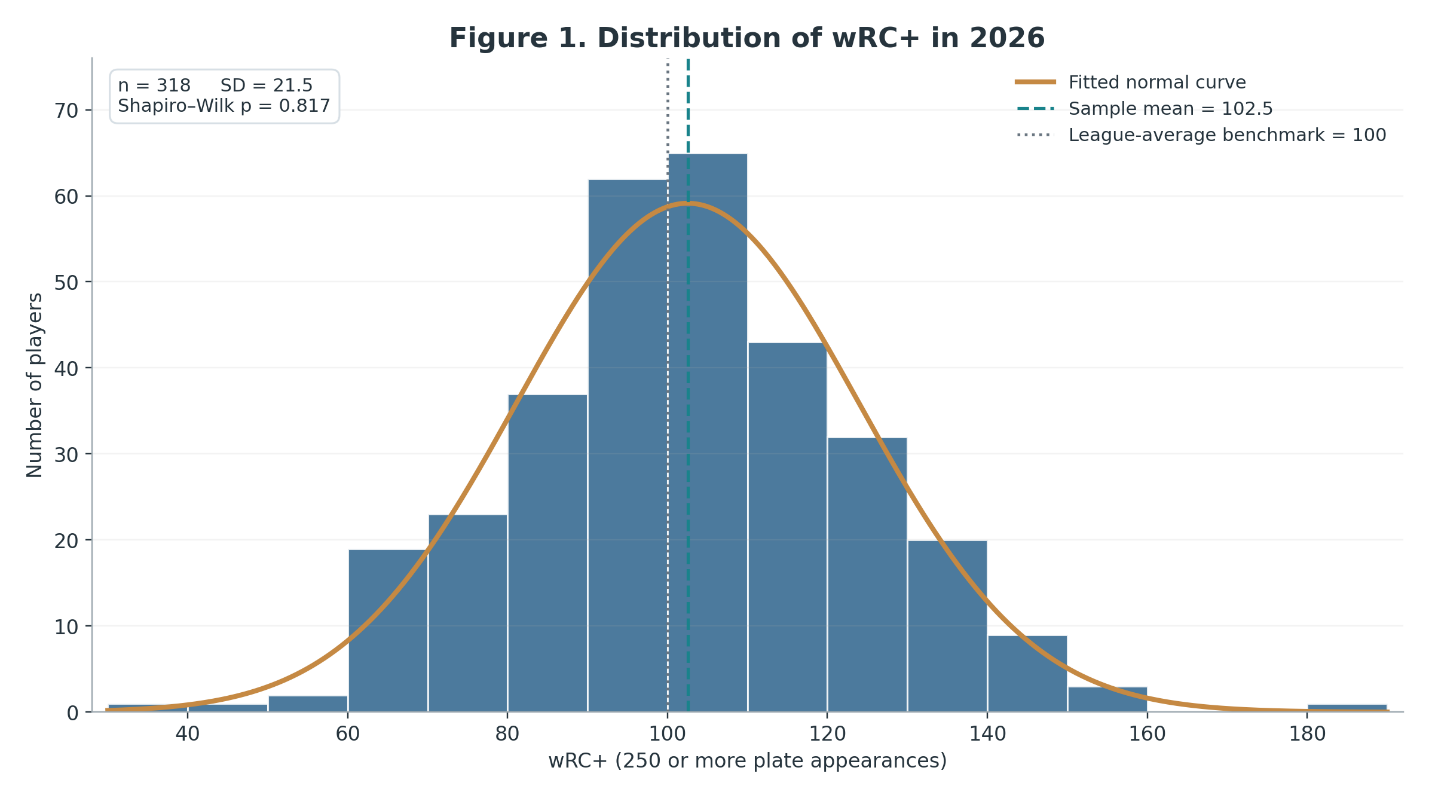
Figure 1. Distribution of wRC+ among players with at least 250 PA

The histogram shows a distribution that closely resembles the familiar bell curve. Kind of beautiful, isn’t it?

I also performed a Shapiro-Wilk normality test.

The result was:

At the conventional significance level of 0.05, we cannot reject the hypothesis that the observations came from a normally distributed population. This does not prove that offensive performance follows a normal distribution. Nevertheless, the descriptive statistics, histogram, and formal test all support approximate normality within this selected group. That gives us a useful starting point for identifying unusually good and unusually poor offensive seasons.

What happens when we change the qualification threshold?

This is where the analysis becomes particularly revealing.

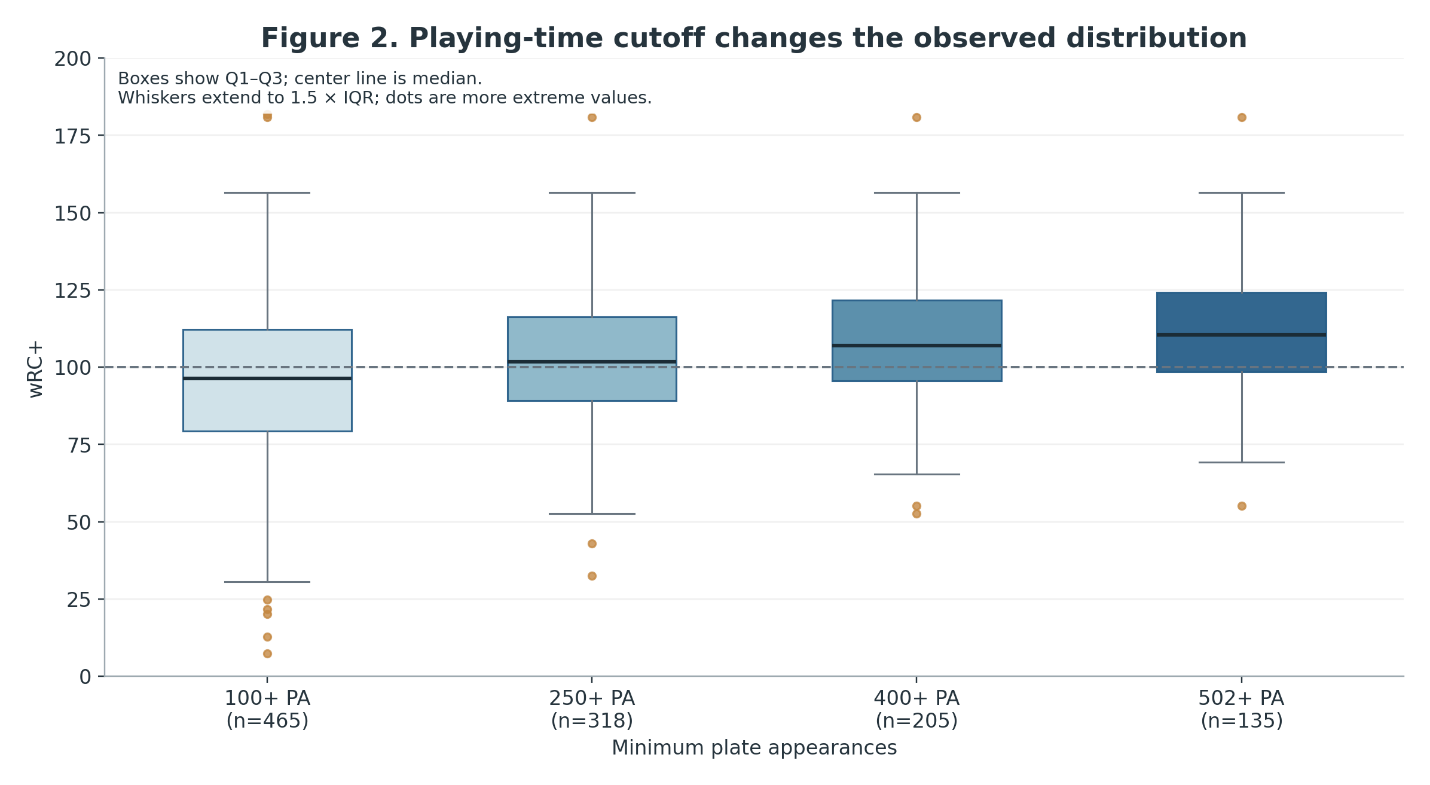
Figure 2. Box plots by minimum plate appearances

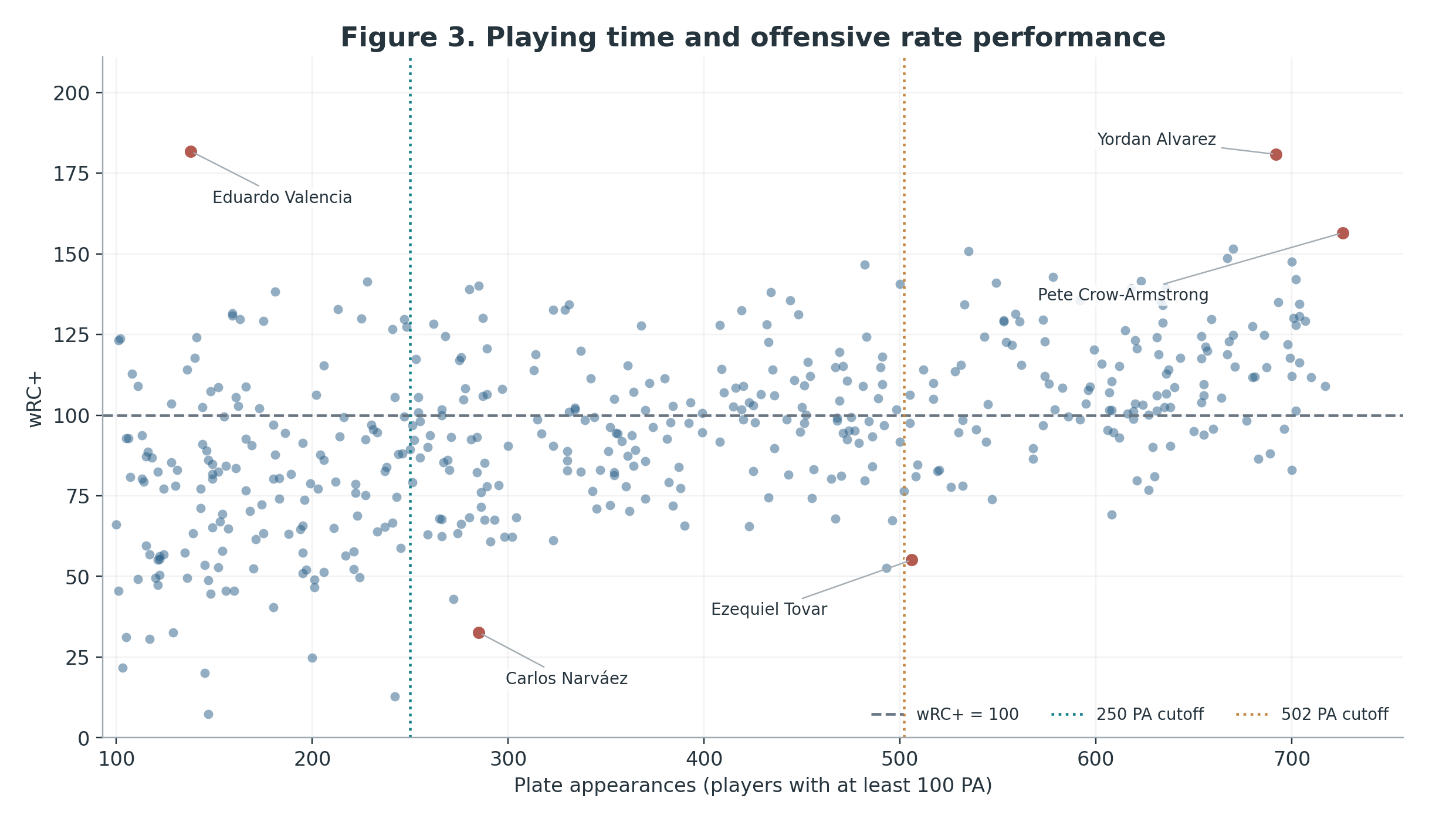
These box plots have a story to tell. As the qualification threshold increases, the entire distribution shifts upward. The median moves from approximately 96 wRC+ among players with at least 100 plate appearances to approximately 111 among players with at least 502. At the same time, the lower tail becomes less extreme.

This suggests that playing time is strongly associated with offensive performance, although the relationship does not establish causation.

We must also remember that these groups overlap. The 502-PA sample is contained within the 400-PA sample, which is itself contained within the 250-PA sample.

Figure 3. Plate appearances versus offensive performance

This scatterplot makes the relationship clearer.

Among the 465 players with at least 100 plate appearances, the Pearson correlation between PA and wRC+ is approximately:

That is a moderate positive association. Players accumulating more plate appearances generally have better offensive statistics. However, this does not mean more plate appearances make a player a better hitter. Rather, teams are likely to give more opportunities to players who perform better. Injuries, defensive contributions, contracts, and roster decisions also influence playing time. This distinction will become especially important when we begin constructing regression models.

Identifying the best offensive performances

We can now begin identifying the extremes of the distribution.

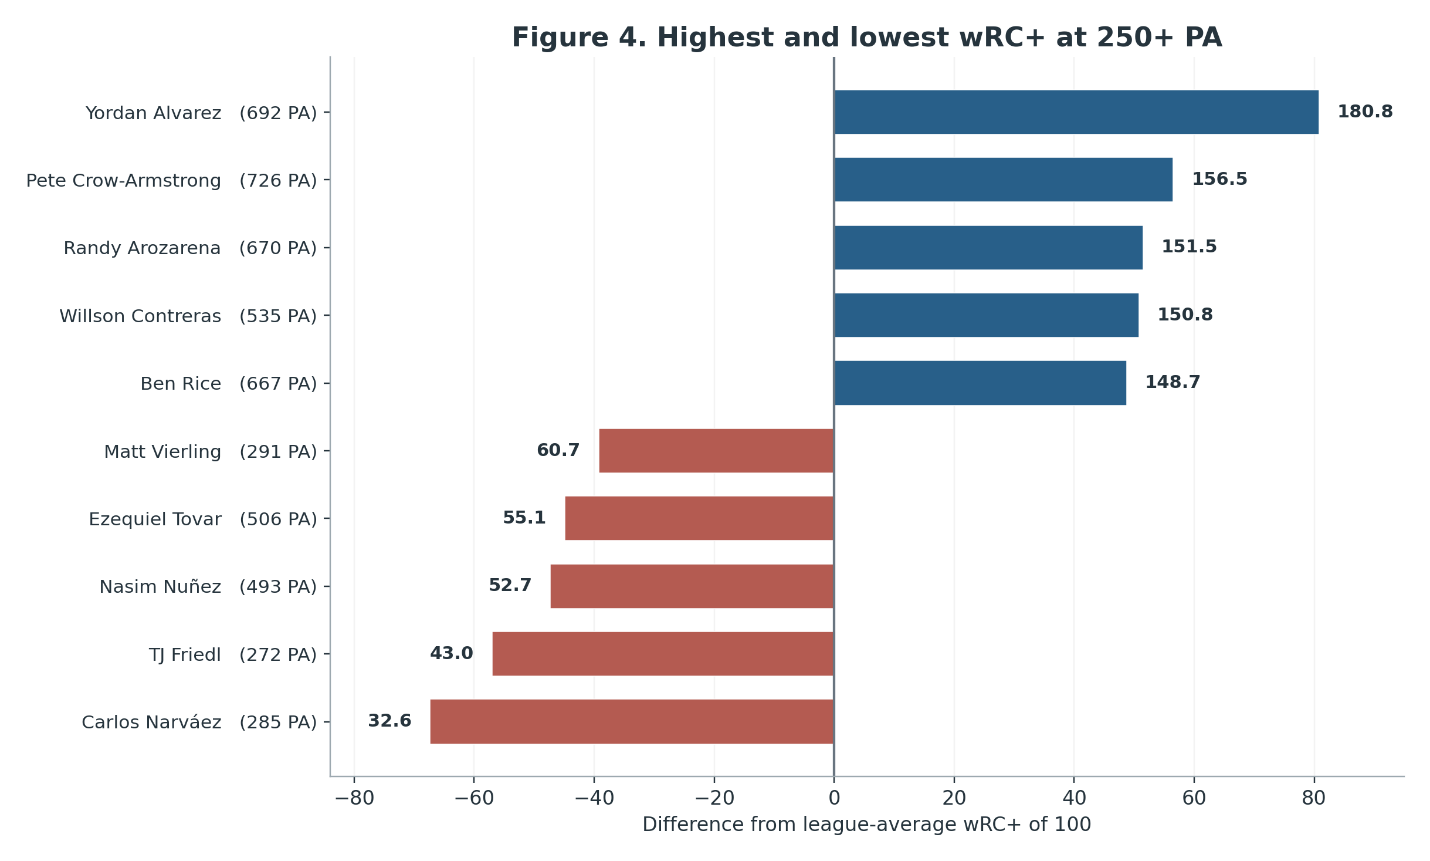
Using our primary 250-PA threshold, the five highest wRC+ performances were:

Player PA wRC+
Yordan Alvarez 692 180.82
Pete Crow-Armstrong 726 156.52
Randy Arozarena 670 151.48
Willson Contreras 535 150.78
Ben Rice 667 148.72

Alvarez stands comfortably ahead of the rest. His wRC+ of 180.82 indicates offensive production per plate appearance approximately 81% above the league-average benchmark after the adjustments incorporated into wRC+. He is also an exceptionally unusual observation within our selected population.

Using the familiar box-plot definition of an outlier, we obtain an upper fence of approximately 156.74. Alvarez exceeds that threshold. Interestingly, Crow-Armstrong, with a wRC+ of 156.52, falls just below it.

The worst offensive performances

At the opposite extreme:

Player PA wRC+
Carlos Narváez 285 32.62
TJ Friedl 272 43.00
Nasim Nuñez 493 52.69
Ezequiel Tovar 506 55.12
Matt Vierling 291 60.74

Narváez and Friedl fall below the conventional lower outlier fence of approximately 48.71. Thus, using the 1.5 × IQR criterion, we identify three statistical outliers in our 318-player sample: one exceptionally high and two exceptionally low.

Figure 4. The extremes of offensive performance

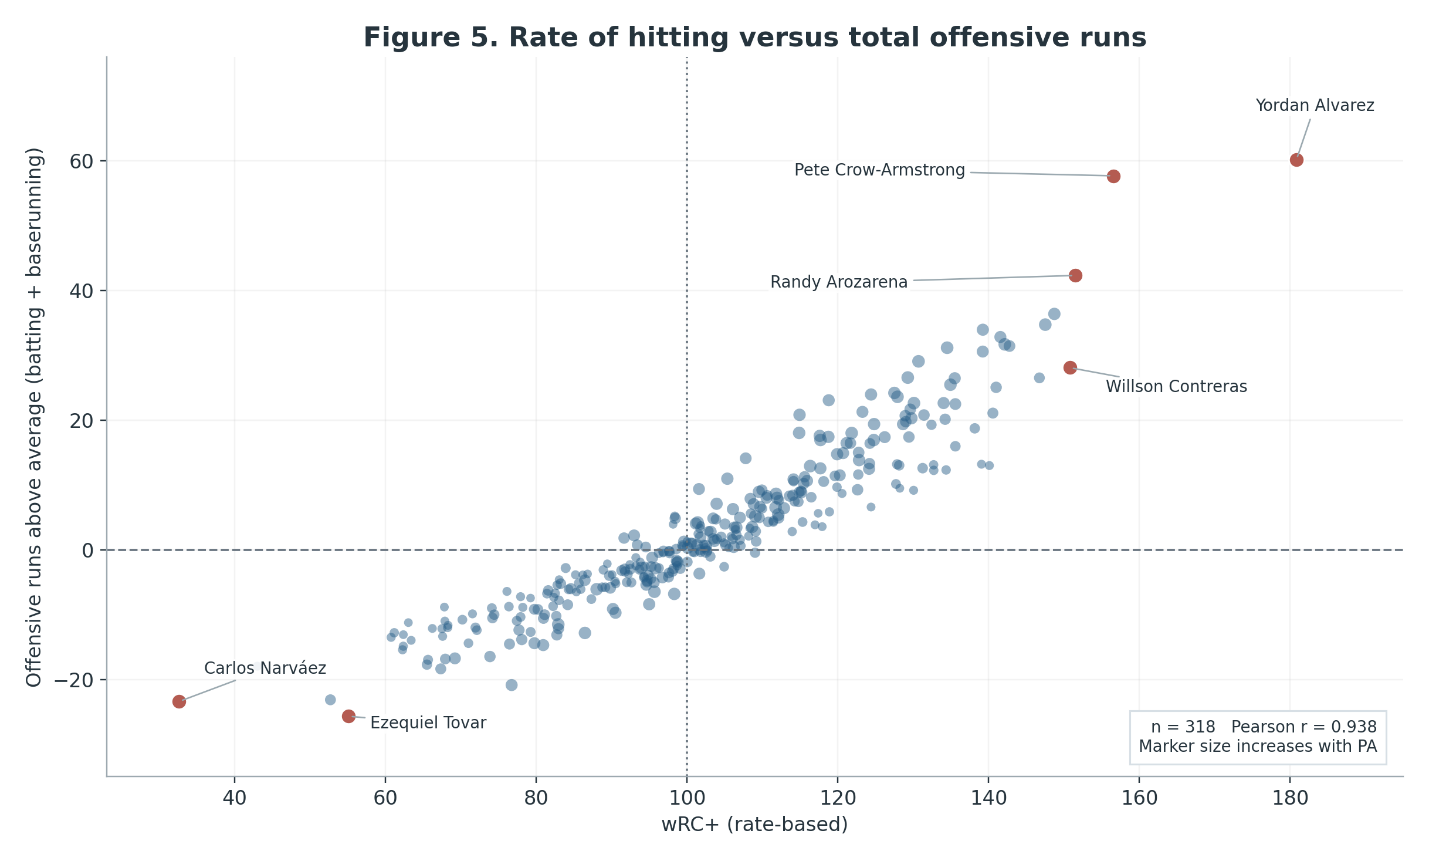
These rankings are based on offensive rate performance. They do not necessarily identify the players who contributed the most or fewest total offensive runs. That distinction is our next important finding.

Offensive excellence versus offensive contribution

Consider the following comparison.

Yordan Alvarez recorded a wRC+ of 180.82 over 692 plate appearances.

Pete Crow-Armstrong recorded a wRC+ of 156.52 over 726 plate appearances.

Alvarez was substantially better as a hitter on a rate basis. However, the difference between their total offensive contributions was much smaller.

Player wRC+ Offensive Runs
Yordan Alvarez 180.82 +60.14
Pete Crow-Armstrong 156.52 +57.68
Randy Arozarena 151.48 +42.31
Ben Rice 148.72 +36.38
Pete Alonso 147.51 +34.73

Why?

Because FanGraphs’ Off statistic includes both batting and baserunning contributions. Alvarez’s extraordinary hitting performance was partially offset by negative baserunning value. Crow-Armstrong, meanwhile, accumulated substantial positive baserunning value.

This illustrates the importance of distinguishing among batting ability, offensive rate performance, and cumulative offensive contribution.

Figure 5. Offensive rate performance versus total offensive contribution

The relationship is extremely strong.

Among the 318 players with at least 250 plate appearances:

Players with higher wRC+ generally accumulate more total offensive runs. However, these measures are not independent. They share underlying batting information, and total offensive runs also depend on opportunities and baserunning. Consequently, the high correlation is expected. It should not be interpreted as evidence that wRC+ predicts Off independently.

The most interesting players may actually be those who deviate from the general relationship. Crow-Armstrong is an excellent example.

6. What about the worst cumulative offensive performances?

Here the rankings change.

Among players with at least 250 plate appearances, the lowest total offensive contributions were:

Player PA wRC+ Offensive Runs
Ezequiel Tovar 506 55.12 -25.67
Carlos Narváez 285 32.62 -23.39
Nasim Nuñez 493 52.69 -23.14
Salvador Perez 627 76.72 -20.86
Matt McLain 496 67.33 -18.37

This illustrates why identifying the worst offensive season requires some methodological care. Carlos Narváez had the lowest wRC+ among players meeting our 250-PA threshold. However, Ezequiel Tovar accumulated the largest negative offensive contribution. Tovar was not the least effective hitter per plate appearance, but he accumulated substantially more playing time.

In other words, the worst offensive rate performance and the greatest cumulative offensive deficit are not necessarily produced by the same player. That is a distinction worth preserving throughout this project.

Some preliminary conclusions

Five important findings have emerged.

First, offensive performance among MLB players meeting moderate playing-time thresholds appears approximately normally distributed.

Second, the distribution changes considerably as we adjust the qualification threshold. This means that rankings, averages, and outlier classifications are sensitive to how we define the population.

Third, Yordan Alvarez clearly distinguished himself as the outstanding offensive-rate performer among players receiving substantial playing time. His performance is also a statistical high outlier using our primary sample.

Fourth, the distinction between hitting effectiveness and total offensive contribution matters. Exceptional baserunning can considerably change a player’s total offensive value.

Finally, players with more plate appearances tend to have better offensive statistics. This suggests that any attempt to model offensive performance needs to consider playing-time selection effects.

A methodological caution

We should keep one additional issue in mind. The closer agreement with a normal distribution at higher PA thresholds does not necessarily reveal the natural underlying distribution of hitting ability. We are observing a selected population. Its composition depends partly on decisions made by managers, front offices, and players themselves.

Thus, the distribution of observed offensive performance is not necessarily identical to the distribution of underlying offensive talent. That distinction could become important in subsequent studies.


October 24, 2026: A Right Triangle on the Calendar

Today’s date, written in the familiar American shorthand, is 10/24/26. At first glance, there is nothing particularly remarkable about it. But square those three numbers, and a familiar relationship emerges:

10^2 + 24^2 = 26^2

The arithmetic works out neatly. One hundred plus 576 equals 676. Today’s date forms a Pythagorean triple, a set of three positive integers that can serve as the side lengths of a right triangle.

That gives October 24 a small mathematical distinction. The calendar has handed us a geometry problem with the answer already attached.

A Familiar Triangle in Disguise

Most of us first encountered the Pythagorean theorem in school. For a right triangle, the sum of the squares of the two shorter sides equals the square of the longest side, called the hypotenuse:

a^2 + b^2 = c^2

The theorem applies whether the side lengths are whole numbers, fractions, or irrational numbers. Pythagorean triples are the special cases in which all three lengths are positive integers. The most familiar example is probably 3, 4, 5. Another is 5, 12, 13.

That second triple explains today’s date. Divide each of our three numbers by two:

(10,24,26) = 2(5,12,13)

Our calendar triangle is a scaled version of the 5-12-13 triangle. Every side has doubled, while the angles remain unchanged. The two triangles are similar, although the larger one has four times the area.

Mathematicians call 5, 12, 13 a primitive Pythagorean triple because the three numbers have no common divisor greater than one. The triple 10, 24, 26 is not primitive. It belongs to the same family, enlarged by a common multiplier.

Where the Numbers Come From

Pythagorean triples can seem like numerical accidents when encountered one at a time. Yet there is a systematic way to generate them. For positive integers , the following expressions produce a Pythagorean triple:

a=m^2-n^2,\qquad b=2mn,\qquad c=m^2+n^2

Choose 3 for and 2 for . The first expression gives 9 minus 4, or 5. The second gives 12. The third gives 9 plus 4, or 13. Double those results, and we arrive at 10, 24, 26.

The formula works because of an algebraic identity:

(m^2-n^2)^2+(2mn)^2=(m^2+n^2)^2

Expanding the left side reveals why. The negative middle term from the first square is offset by part of the second term, leaving exactly the expansion of the expression on the right. What initially looks like a lucky match turns out to follow from a general relationship.

There are infinitely many Pythagorean triples. Dates, however, impose much tighter restrictions. A month cannot exceed 12, and a day cannot exceed 31. Only a small portion of that infinite mathematical landscape can fit onto a calendar.

The Calendar Supplies the Coincidence

There is a qualification here. The pattern depends on how we write the date. We use 26 for the year rather than 2026. In a day-first format, the date becomes 24/10/26, which preserves the relationship because exchanging the two shorter sides changes nothing.

Writing the full year removes this particular pattern:

10^2+24^2\ne2026^2

That dependence on notation is part of the appeal. The calendar does not possess some hidden geometric force. We have chosen a way of recording dates that occasionally places meaningful numerical relationships in front of us.

Recognizing that distinction lets us enjoy the coincidence without asking it to explain more than it does. There is no reason to expect today’s events to follow a special course because its abbreviated date describes a right triangle. There is, however, a good reason to pause over the arithmetic.

A Small Invitation to Notice

I like these moments because they make familiar ideas briefly unfamiliar again. A theorem remembered from school appears in the corner of a computer screen. Three ordinary numbers become the sides of a triangle. A date becomes an invitation to investigate.

Following that invitation takes us from arithmetic to geometry, then to scaling, algebra, and the distinction between a pattern and the notation that reveals it. That is a respectable amount of mathematics to find in a date.

October 24, 2026, will pass like any other day. For a moment, though, we can picture it as a triangle: ten units across, twenty-four units up, and twenty-six units along the diagonal. The numbers fit, and noticing why is a pleasure.

Postscript

Check this out. We will have to wait a while for the next one.

Occasion Date Pythagorean relationship
Previous July 24, 2025 7² + 24² = 25²
Today October 24, 2026 10² + 24² = 26²
Next March 4, 2105 3² + 4² = 5²

So today is the last such date this century. The next is more than 78 years away, followed shortly by April 3, 2105, which reverses the two shorter sides. Not bad, in fact, that is pretty cool.


What Did an MLB Win Cost in 2026?

What Did an MLB Win Cost in 2026?

There is another way to look at the relationship between payroll and winning. Instead of asking whether higher payroll produces more victories, we can ask a simpler question: How much did each team spend for each win?

For each club, I calculated:

\mathrm{Payroll\ Cost\ per\ Win} = \frac{\mathrm{Total\ Payroll}}{\mathrm{Wins}}

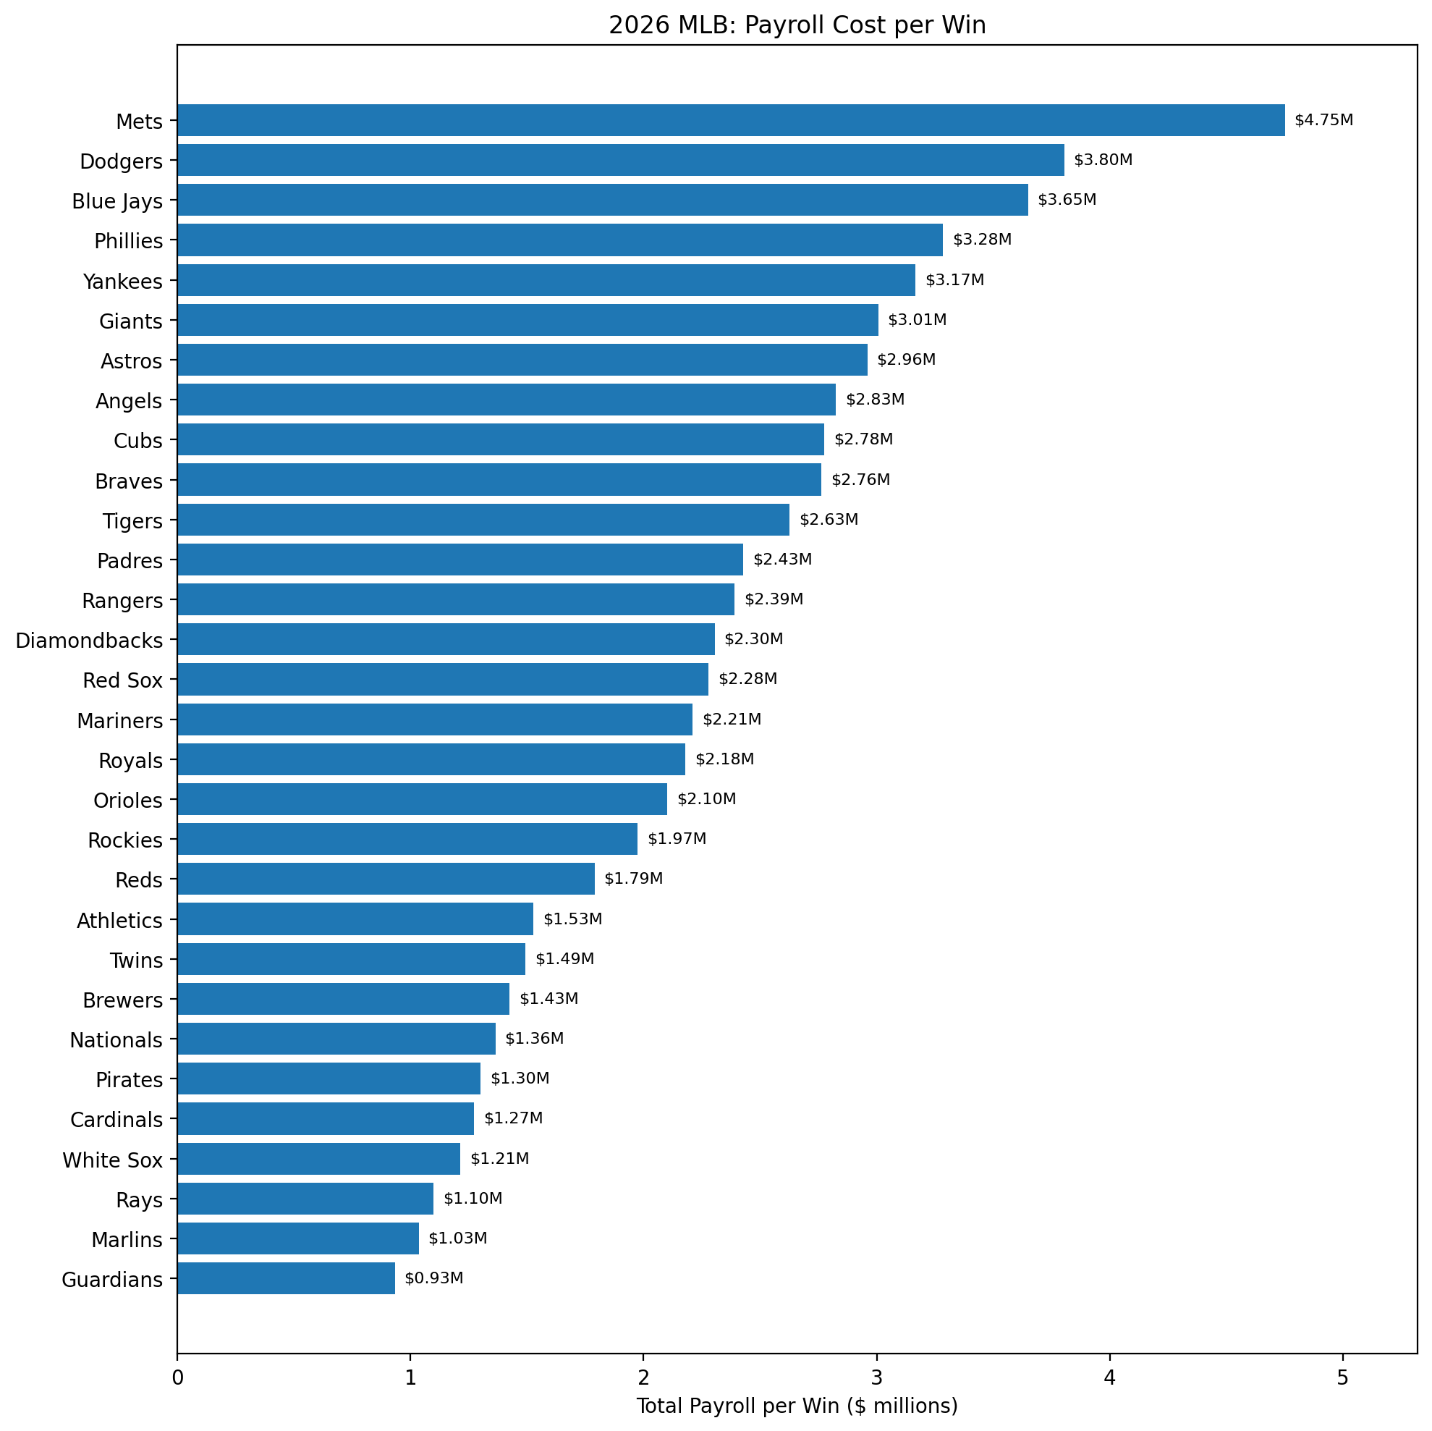
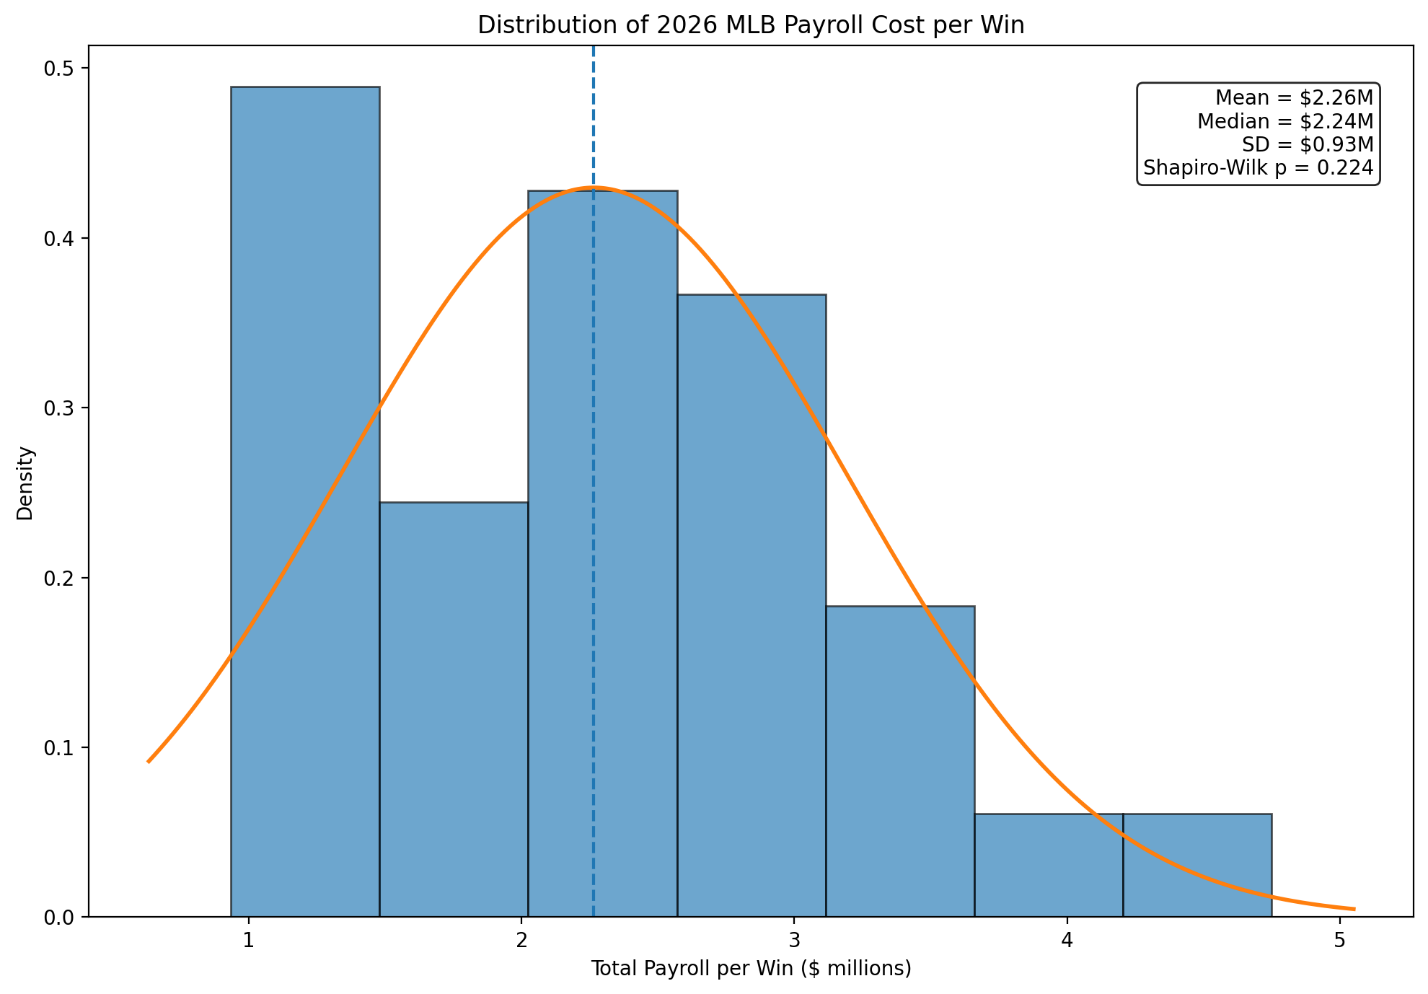
Across the 30 MLB teams in 2026, the average cost was about $2.26 million per win. The median was almost identical at $2.24 million, with a standard deviation of approximately $0.93 million.

But the range was enormous.

Cleveland (surprised?) produced wins at the lowest monetary cost, spending only about $0.93 million per victory. Miami followed at roughly $1.03 million, with Tampa Bay at $1.10 million.

At the opposite end, the Mets spent approximately $4.75 million for every win. The Dodgers were next at $3.80 million, followed by Toronto at about $3.65 million.

Figure 1. Payroll Cost per Win

The rankings produce some interesting contrasts.

Milwaukee won 103 games while spending only about $1.43 million per win. Tampa Bay won 98 at approximately $1.10 million per win. Cleveland won 85 despite having the lowest total payroll in baseball.

Meanwhile, large payrolls did not necessarily translate into inexpensive victories. The Mets’ $351.6 million payroll combined with only 74 wins produced the highest cost per victory in MLB.

Does Cost per Win Follow a Normal Distribution?

This is where the analysis becomes especially interesting.

The distribution is surprisingly close to a normal distribution, although it has a modest right-hand tail.

The descriptive statistics are:

\mathrm{Mean} = \$2.264\ \mathrm{million} \mathrm{Median} = \$2.244\ \mathrm{million} \mathrm{SD} = \$0.929\ \mathrm{million}

The mean and median being so close is our first indication that the distribution is reasonably balanced.

The measured skewness was:

\mathrm{Skewness} = 0.625

So the distribution is somewhat right-skewed, largely because of the very expensive wins produced by teams such as the Mets, Dodgers, and Blue Jays.

Figure 2. Distribution of Payroll Cost per Win

Visually, the normal curve fits the data reasonably well.

More importantly, a Shapiro-Wilk test gives:

W = 0.955 p = 0.224

A D’Agostino-Pearson normality test produces a similar result:

p = 0.293

Provides sufficient evidence to reject the hypothesis that the 30 values came from a normal distribution.

That does not prove that MLB cost per win is normally distributed. Thirty teams constitute a relatively small sample, and the right tail is clearly visible.

Still, the result is intriguing. For 2026, team spending per victory forms something surprisingly close to the familiar bell-shaped distribution.

Most teams cluster around roughly $1.5 million to $3 million per win, with a few exceptionally inexpensive winners on one side and a few extraordinarily expensive victories on the other.

Perhaps the next question is the most interesting one: does this normal-looking distribution appear every season, or is 2026 unusual?


Money Helps, but Not as Much as You Might Think: MLB Payroll and Wins in 2026

Money Helps, but Not as Much as You Might Think: MLB Payroll and Wins in 2026

Baseball has always lived with an uncomfortable question: how many wins can a team buy?

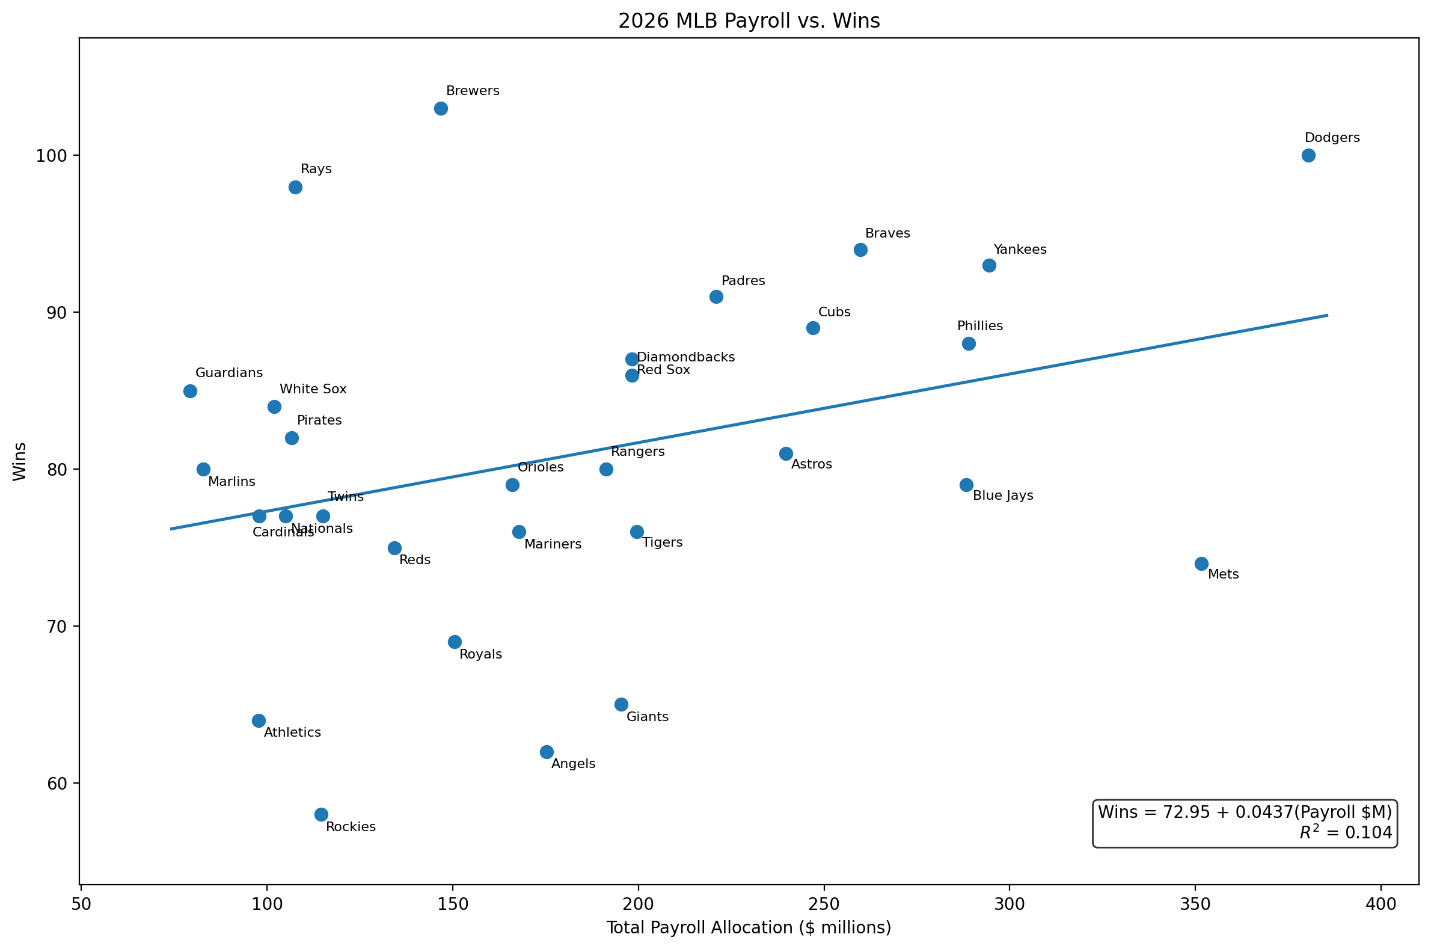
The 2026 season gives us another opportunity to look at that question. Using Spotrac’s total payroll allocations for all 30 MLB teams and each club’s final win total, we can compare spending directly with performance.

The relationship exists, barely. It is not particularly strong.

The average MLB payroll in 2026 was approximately $183.4 million, while the median was about $171.5 million. At the extremes, the Dodgers spent roughly $380.4 million, while Cleveland operated with only $79.3 million.

Yet those differences in spending did not translate neatly into differences in wins.

The simple linear regression is:

\mathrm{Wins} = 72.95 + 0.0437 \left( \mathrm{Payroll\ in\ \$Millions} \right)

The correlation between payroll and wins was:

r = 0.323

and the coefficient of determination was:

R^2 = 0.104

In other words, payroll explained only about 10.4 percent of the variation in team wins during the 2026 season. That is surprisingly little.

The regression coefficient provides another way to see it. An additional $100 million in payroll was associated with only about 4.4 additional wins. Even that relationship was not conventionally statistically significant, with .

Figure 1. Payroll and Wins


Figure 1 shows why the relationship is so weak. There is a slight upward trend, but the teams are widely scattered around the regression line.

Milwaukee is perhaps the most striking example. The Brewers won 103 games with a payroll of about $146.8 million. Tampa Bay won 98 games while spending only about $107.6 million.

Cleveland provides another interesting case. The Guardians had the lowest payroll in baseball, approximately $79.3 million, yet still won 85 games. At the opposite end, the Mets spent approximately $351.6 million and won only 74 games.

Money is important, but these teams show how much room remains for roster construction, player development, injuries, aging, unexpected breakouts, and simple baseball variance.

Measuring Payroll Efficiency

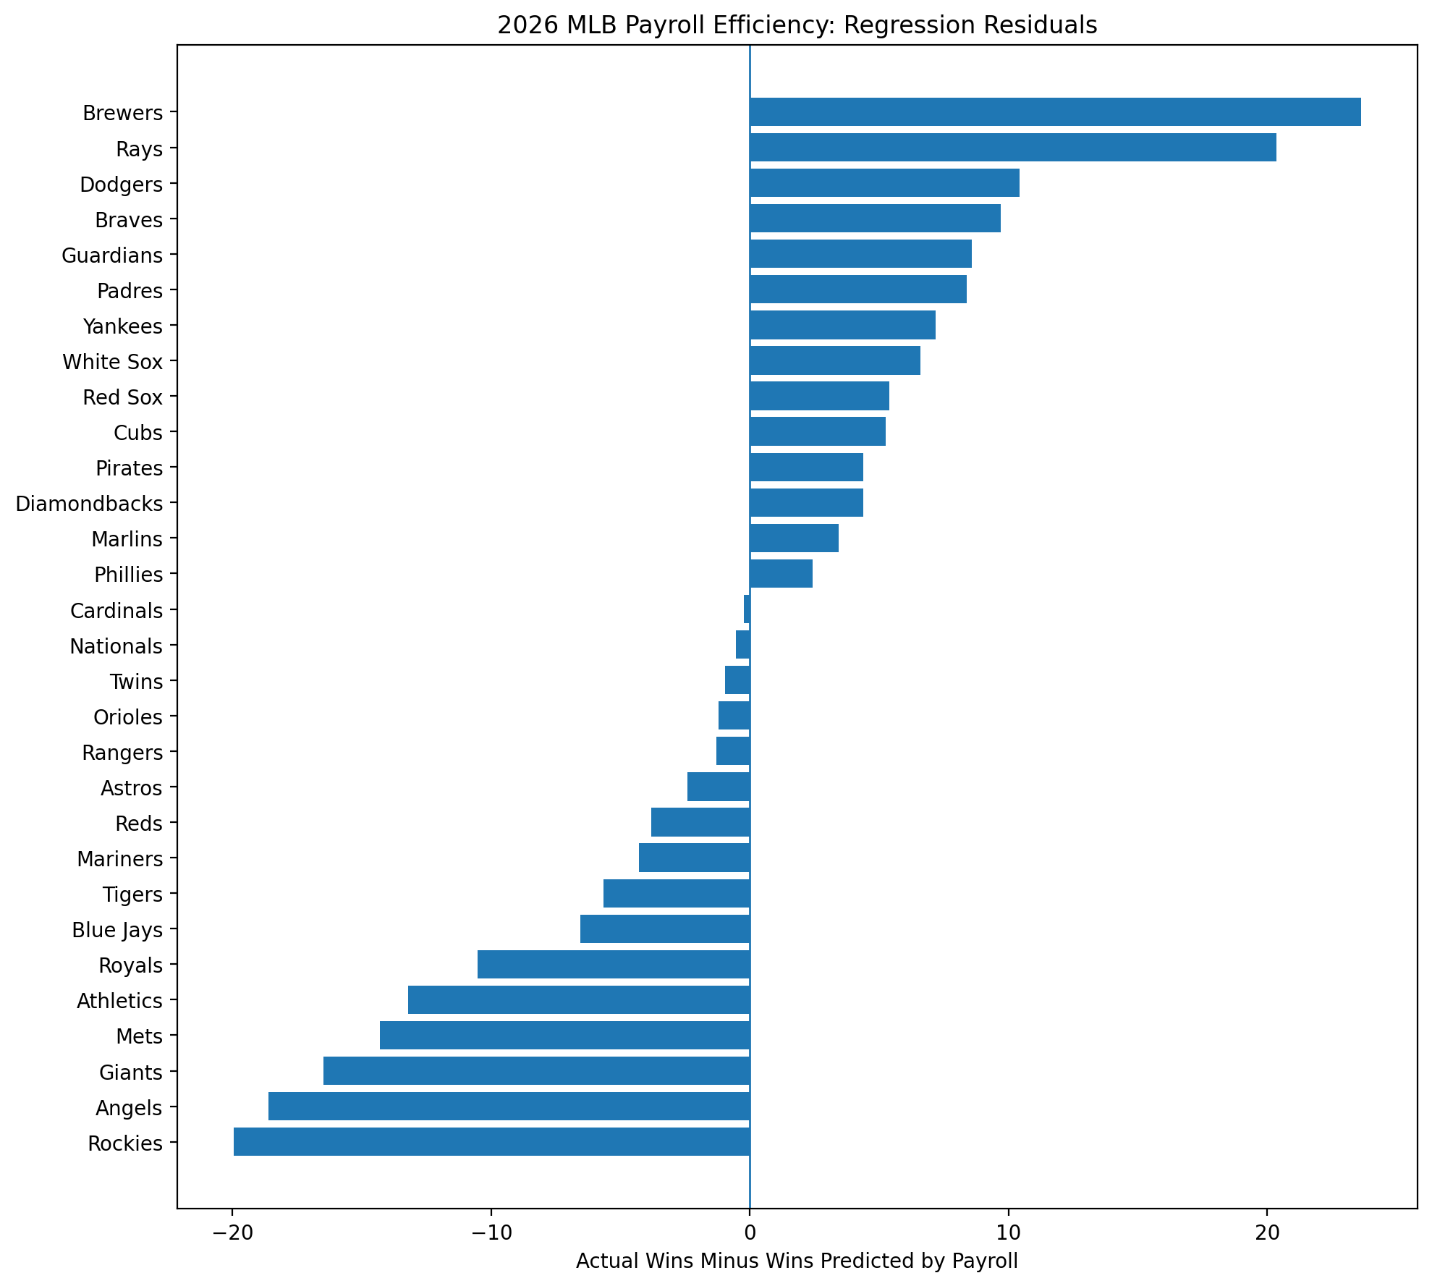
Rather than simply dividing payroll by wins, we can use the regression model to ask a better question: How many games did a team win compared with the number of wins we would expect from its payroll?

The difference between actual wins and predicted wins is the regression residual.

A positive residual means the team won more games than its payroll would predict. A negative residual means it won fewer.

Figure 2. Wins Above or Below Payroll Expectations

The Brewers were the extraordinary outlier, finishing about 23.6 wins above their payroll-based expectation. Tampa Bay followed at roughly 20.4 wins above expectation.

The Dodgers also performed well relative to their enormous payroll, finishing about 10.4 wins above the regression prediction. Atlanta was about 9.7 wins above expectation, while Cleveland finished approximately 8.6 wins above expectation.

At the other end were Colorado, the Angels, San Francisco, and the Mets. Each won far fewer games than its payroll predicted.

That distinction is noteworthy. A large payroll is not automatically inefficient. The Dodgers spent more than anyone else, but they also won 100 games and substantially exceeded the performance predicted by the league-wide payroll relationship.

Likewise, a small payroll is not automatically efficient. A low-spending team still has to win.

What 2026 Tells Us

The 2026 season reinforces something we have seen repeatedly in studying baseball economics. Payroll establishes possibilities. It does not determine outcomes.

Teams with greater financial resources can purchase more established talent, absorb expensive mistakes, replace injured players, and retain stars. Those advantages are real.

But across MLB in 2026, nearly 90 percent of the variation in wins was associated with factors other than payroll in this simple model.

Milwaukee, Tampa Bay, and Cleveland dramatically exceeded what their payrolls alone would suggest. The Mets demonstrated the opposite problem: enormous financial resources did not translate into comparable success.

For a sport supposedly divided between the rich and everyone else, the 2026 scatterplot is remarkably messy. And that may be the most interesting result of all.


The Men in the Middle: Who Was the Best Shortstop of the 1970s?

The shortstop position in the 1970s was very different from what we know today. Power was welcome, of course, but it was hardly the defining requirement. Teams generally expected their shortstops to catch the ball, make the throw, turn the double play, move runners when necessary, and contribute enough offensively to keep the lineup moving.

That makes the decade particularly interesting to study. There was no Cal Ripken Jr. yet, no Alex Rodriguez, no Derek Jeter, and certainly no modern collection of 25-home-run shortstops scattered throughout the league. The position still leaned heavily toward defense, speed, contact, and durability.

But who was actually the best?

The familiar names arrive quickly. Dave Concepción was the shortstop of the Big Red Machine. Mark Belanger was one of the most celebrated defensive players of his generation. Bert Campaneris brought speed and range to the Oakland dynasty. Larry Bowa became synonymous with Philadelphia baseball. Chris Speier, Don Kessinger, Freddie Patek, Rick Burleson, Toby Harrah, and others all made substantial claims of their own.

Rather than begin with reputation, I wanted to begin with the data. The result was clear at the top. The more interesting story, however, was what happened immediately behind the winner.

Defining a 1970s Shortstop

The study covers the seasons from 1970 through 1979. Players were identified by their appearances at shortstop, and the primary requirement was at least three qualifying shortstop seasons during the decade.

That qualification matters. A player who happened to spend one excellent season at shortstop should not necessarily outrank someone who occupied the position for most of the decade. At the same time, requiring eight or ten seasons would unfairly eliminate players whose careers began midway through the 1970s.

The three-season minimum produced a pool of 34 shortstops. As a sensitivity check, I later tightened the requirement to five qualifying seasons. The top five did not change, which matters when we consider how robust the final ranking really is.

The offensive model follows the same peer-adjusted Model C framework I have used in earlier positional studies. Each shortstop is compared with other shortstops from his own season rather than with hitters from another position or another era. The underlying model incorporates on-base percentage, isolated power, walk rate, strikeout avoidance, baserunning, runs scored, and RBI production.

For WordPress, the equation is:

\begin{aligned} \mathrm{OffensiveScore} &= z_{\mathrm{OBP}} + z_{\mathrm{ISO}} + z_{\mathrm{BB/PA}} + z_{\mathrm{LowSO/PA}} \\ &\quad + z_{\mathrm{NetSB/PA}} + z_{\mathrm{R/PA}} + z_{\mathrm{RBI/PA}} \end{aligned}

This approach changes the question in an important way. It does not ask whether Freddie Patek hit like a first baseman. He obviously did not. It asks how much offensive value Patek produced relative to the other men being asked to play shortstop at the same time.

Defense presents a more difficult problem.

The Lahman database gives us traditional fielding information, including assists, putouts, double plays, errors, games, and fielding percentage. It cannot provide the spatial information available in modern systems such as Outs Above Average, nor can it fully separate a shortstop from the pitchers, second basemen, field conditions, positioning, and scoring practices around him.

Still, we can construct a useful traditional defensive index:

\mathrm{TraditionalDefensiveScore} = z_{\mathrm{A/G}} + z_{\mathrm{PO/G}} + z_{\mathrm{DP/G}} + z_{\mathrm{FPct}} + z_{\mathrm{LowE/G}}

This is the same general traditional-defense construction used in our earlier positional work. It should be interpreted as a measure of performance in the defensive statistics available to us, not as a retroactive version of modern defensive runs saved.

Once the offensive and defensive dimensions were calculated, each was standardized and combined:

\mathrm{TwoWayScore}_{i} = z_{\mathrm{Offense},i} + z_{\mathrm{Defense},i}

That is the key to the study. We are not looking for the best hitter who happened to stand at shortstop, nor simply for the slickest glove. We are looking for the player who best combined the position’s two demands.

The First Answer

The ranking produces an unusually satisfying No. 1. Dave Concepción finishes first.

He is not first because the algorithm happens to reward longevity. He is also not first because of one extraordinary short peak. Concepción ranks first in overall two-way performance and first when the calculation is restricted to the best three-season peak. Offensively, he ranks second among the qualifying shortstops, while his traditional defense ranks fifth.

Figure 1. Best Shortstops of the 1970s: Two-Way Career Ranking.

Figure 1 shows how much separation Concepción creates. His standardized two-way career score of 3.36 comfortably exceeds Freddie Patek at 2.70 and Chris Speier at 2.55. Larry Bowa follows at 2.19, with Bert Campaneris rounding out the top five at 1.68.

The complete top ten is revealing:

Rank Player Offensive Rank Defensive Rank Peak Rank
1 Dave Concepción 2 5 1
2 Freddie Patek 3 7 2
3 Chris Speier 4 6 3
4 Larry Bowa 16 1 7
5 Bert Campaneris 5 12 8
6 Roy Smalley 6 13 4
7 Toby Harrah 1 27 6
8 Mark Belanger 25 2 9
9 Rick Burleson 9 9 5
10 Don Kessinger 7 11 11

The list immediately tells us something important. There was not one model of a successful 1970s shortstop. There were several.

Concepción simply inhabited the most valuable part of that landscape.

Concepción and the Power of Balance

Concepción’s offensive score for the decade is 31.83, second among the group, while his defensive score is 19.88, fifth. His strength is therefore not hidden inside a single category. He rates very well in both.

That balance is visible when offense and defense are plotted separately.

Figure 2. Different Paths to Shortstop Value in the 1970s.

The horizontal dimension in Figure 2 represents peer-adjusted offense. The vertical dimension represents traditional defense. Players in the upper-right portion of the chart are the rare shortstops who contributed substantially in both areas.

Concepción occupies exactly the region we would hope the best shortstop would occupy. Chris Speier and Freddie Patek are nearby, though neither reaches quite as far offensively. The graph makes Concepción’s advantage easier to understand than a ranking alone can.

It also reveals something much more interesting about the rest of the decade.

Larry Bowa and Mark Belanger live high on the defensive axis. Toby Harrah sits far to the right offensively but dramatically lower defensively. Freddie Patek, Chris Speier, Bert Campaneris, and Roy Smalley occupy a more balanced middle ground.

Different players reached value by very different routes.

The Freddie Patek Problem

If anything in this study surprised me, it wasn’t Concepción finishing first. It is Freddie Patek finishing second.

Patek ranks third offensively, seventh defensively, second in three-year peak, and second overall. His two-way career score of 2.70 places him ahead of Speier, Bowa, Campaneris, and Belanger.

That doesn’t look obvious if we start with conventional batting statistics. Patek was not a slugger. He did not put up the sort of raw offensive totals that jump from a baseball card.

But that is exactly why positional and seasonal context matter. Patek was being compared with other 1970s shortstops, not with Reggie Jackson or Willie Stargell. His ability to get on base, create runs with his legs, avoid being a complete offensive liability, and still provide useful defense matters more when evaluated against his positional peers.

The model does not claim that Patek was one of the best hitters in baseball. It says something narrower and more interesting: relative to what teams were receiving from shortstop, Freddie Patek created a surprisingly large amount of value.

That distinction is essential.

Chris Speier: The Quietly Complete Shortstop

Patek may be the surprise, but Chris Speier might be the cleanest example of an underrated two-way player.

Speier ranks fourth offensively and sixth defensively. Those rankings combine to place him third overall, and he is also third in three-season peak.

There is nothing extreme about his statistical profile. That is precisely what makes him interesting.

He does not need Harrah’s offensive advantage. He does not need Belanger’s defensive advantage. Speier remains near the top because there is no obvious weakness in his profile relative to other shortstops of the decade.

Baseball history sometimes remembers specialists more vividly than balanced players. Extraordinary power is memorable. Extraordinary defense produces highlight plays and reputations. A player who is simply very good at everything can be easier to overlook.

Speier appears to have been that kind of shortstop.

Larry Bowa and Mark Belanger

Now the geometry changes. Larry Bowa ranks only 16th offensively, but he finishes first defensively in the traditional model. The strength of that defense is sufficient to elevate him to fourth overall.

Mark Belanger pushes the idea even further. His offense ranks 25th, near the bottom of the serious candidates, but his defense ranks second. The combination still carries him all the way to eighth overall.

This is where the external evidence becomes particularly useful. Belanger won seven Gold Gloves during the decade. The Gold Gloves are not part of the model. They were added only after the rankings were calculated, so the agreement between the traditional defensive score and contemporary recognition serves as a useful independent check.

It does not prove that our defensive score measures everything correctly. Nothing built from traditional fielding statistics could. But if a model designed to detect exceptional traditional defense places Mark Belanger near the top, and contemporary observers repeatedly reached the same conclusion, that is reassuring.

Toby Harrah and the Other Extreme

If Bowa and Belanger demonstrate how defense can carry a shortstop, Toby Harrah demonstrates the opposite.

Harrah ranks first offensively among the qualifying shortstops of the decade. Defensively, however, he falls to 27th. That combination leaves him seventh overall, despite having the strongest offensive score in the study.

That makes Harrah one of the most informative players in the analysis. If we ranked shortstops by offense alone, Harrah would win. If we ranked them by traditional defense alone, Bowa would win. If we ask who combined the two dimensions most successfully, Concepción wins.

Those are three different questions. They deserve three different answers.

Peak Value Changes Less Than Expected

Career rankings can sometimes reward players who were merely good for a long time. A shorter peak measurement helps expose that problem.

For this study, I calculated each player’s best three-season two-way peak. The result strengthens rather than weakens Concepción’s case.

Figure 3. Career Value Versus Peak Value.

Concepción is again first. Patek is second and Speier third, giving us the same top three produced by the decade-long measure.

Roy Smalley becomes especially interesting here. He ranks sixth in decade value but fourth in peak value, despite having only four qualifying offensive seasons in the 1970s. Rick Burleson similarly rises to fifth in peak performance while ranking ninth over the full decade.

That distinction is useful because a decade boundary is artificial. Smalley did not organize his career around our decision to begin counting on January 1, 1970, and stop after the 1979 season. Younger players entering late in the decade naturally have less opportunity to accumulate career value.

Peak analysis gives them a second way into the conversation.

The Clusters of Shortstop Greatness

A ranking forces players onto a line. Baseball players rarely exist on one.

Cluster analysis lets us approach the same group differently. Instead of asking who ranks first, second, or third, we ask which players possess similar statistical profiles.

For Figure 4, we clustered the top 15 shortstops using standardized offensive performance, defensive performance, and three-season peak value.

Figure 4. Similarity Among the Top 15 Shortstops of the 1970s.

The dendrogram reinforces what Figure 2 suggested. Toby Harrah branches away from the more balanced offensive group because of his unusual offense-first profile. Concepción, Patek, and Speier cluster much more naturally with one another, while Bowa and Belanger occupy the defense-heavy side of the landscape.

This is one reason I like clustering for historical baseball analysis. Two players can finish near each other in a ranking without being remotely similar players.

The ranking tells us how much value the model identifies. The dendrogram begins to tell us what kind of player produced it.

What About Contemporary Reputation?

Only after completing the statistical rankings did I bring All-Star selections and Gold Gloves into the study.

The comparison is fascinating. Concepción made six All-Star teams during the decade and won five Gold Gloves. Larry Bowa made five All-Star teams and won two Gold Gloves. Campaneris was selected five times. Belanger, despite only one All-Star selection during the decade, accumulated seven Gold Gloves.

Concepción’s contemporary reputation therefore lines up remarkably well with the model. The statistical system identifies him as the decade’s best all-around shortstop, while the people watching and voting at the time repeatedly recognized both his overall quality and his defense.

Patek provides the more provocative contrast. He made three All-Star teams but won no Gold Gloves, yet the model places him second overall. Speier also made three All-Star teams and won no Gold Gloves during the decade, but finishes third.

Perhaps those players were better than their historical reputations now suggest. Perhaps our model is capturing forms of value that were less likely to produce awards. More likely, it is some combination of both.

Either way, the discrepancy is worth noticing.

Testing the Ranking

Any historical ranking should survive reasonable changes to its assumptions.

The original model required at least three qualifying shortstop seasons. I therefore repeated the ranking with a substantially stricter requirement of five qualifying seasons.

The top five remained unchanged: Dave Concepción, Freddie Patek, Chris Speier, Larry Bowa, and Bert Campaneris.

That stability matters. A ranking that changes dramatically because a cutoff moves from three seasons to five would make me nervous. Here, the central conclusion survives.

Concepción does not win because of an arbitrary eligibility rule. Patek and Speier do not appear near the top because of a tiny sample. Bowa and Campaneris remain firmly in the same group.

The deeper we look, the more stable the top of the ranking becomes.

What the Model Cannot Tell Us

There is still a limit to what we can claim.

Traditional fielding statistics are not modern defensive metrics. Assists depend partly on opportunity. Double plays depend partly on the second baseman and the pitching staff. Fielding percentage cannot tell us whether a defender reached a ball another shortstop would never have touched.

Those limitations become particularly important when interpreting players such as Belanger, Bowa, and Bill Russell. A ranking constructed from traditional fielding data should not be read as a precise estimate of defensive runs saved.

It is better understood as a historical reconstruction from the evidence available.

That is still valuable. The goal is not to pretend we possess Statcast data from 1975. The goal is to combine the surviving information carefully enough that patterns begin to emerge.

And several patterns do.

So, Who Was the Best?

After offense, defense, longevity, peak value, sensitivity testing, and comparison with contemporary recognition, I think the answer is Dave Concepción.

His case is unusually complete. He ranks second offensively, fifth defensively, first overall, and first in three-season peak. He also received substantial contemporary recognition, with six All-Star appearances and five Gold Gloves during the decade.

But the study would be much less interesting if it ended there.

Freddie Patek’s second-place finish may be the most surprising result. Chris Speier emerges as perhaps the most underrated balanced shortstop of the decade. Larry Bowa and Mark Belanger demonstrate the extraordinary value that defense could carry at the position. At the same time, Toby Harrah shows how far outstanding offense could push a shortstop even when his traditional defensive record lagged behind.

That is what I like most about the result.

There was no single template for a great shortstop in the 1970s. Harrah, Belanger, Bowa, Patek, Speier, Campaneris, and Concepción reached value by different paths. The data does not erase those differences by forcing everyone into the same mold.

Instead, it makes the differences visible. And when offense and defense are finally brought together, Dave Concepción is the player standing highest in the middle.